Tsinghua Math Genius Joins OpenAI, Ex-SAM/Llama Lead
A top mathematics talent from Tsinghua University has joined OpenAI. He previously led development of Meta's SAM image segmentation model and Llama large language models.
量子位 · 206d ago
Models that see, hear and speak are replacing text-only systems. Coverage of vision-language models, native audio and video understanding.
354 articles
A top mathematics talent from Tsinghua University has joined OpenAI. He previously led development of Meta's SAM image segmentation model and Llama large language models.
量子位 · 206d ago

Pika, known for AI video, launched AI Selves to create personalized AI clones users can nurture with custom personalities, memories, and details like peanut allergies. These digital selves handle chats, games, calls, and evolve with users across platforms like X and Discord.
机器之心 · 210d ago

DeepSeek Flash 4.1 is reportedly undergoing internal beta testing and rolling out through the API. The intermediate model claims native multimodal support, stronger performance, faster inference, and lower costs, while retaining DeepSeek V4 Flash pricing.
Reddit r/LocalLLaMA · 11d ago
A developer claims to have scraped 5.94 billion TikTok videos and 3.23 billion profiles over three weeks, publishing the video dataset on Hugging Face. The collection includes videos, profiles, comments, replies, hashtags, and sounds, although the scraping method may violate TikTok’s Terms of Service and the full code requires payment.
Reddit r/MachineLearning · 17d ago

Anian is a safety-gated multimodal backend for perinatal mental-health support that routes user input through structured state representation, conservative risk fusion, and controlled response generation. Its prototype reports strong internal classification and routing results, but the authors stress that it does not establish clinical validity, diagnostic accuracy, or real-world safety.
ArXiv AI · 21d ago
神秘模型 OxAlpha 突然上线,声称支持百万级上下文窗口,以及图像、文本和视频的多模态输入输出。该模型目前提供免费输入和输出,但其开发公司和技术来源尚未明确。
虎嗅 · 26d ago

Tencent's Hunyuan Hy4 has reportedly appeared in the model selection list of the Yuanbao app under an expert-level label and with tool-use capabilities. It is positioned above Hy3 and alongside DeepSeek, following Tencent's recent statement that a larger-parameter Hy4 would launch soon with improved performance and multimodal abilities.
Reddit r/LocalLLaMA · 30d ago

Tencent is reportedly reshaping its multimodal AI direction from content generation toward contextual understanding and action in the real world. The shift appears closer to Liang Wenfeng’s emphasis on reasoning and execution, and farther from Fei-Fei Li’s world-model-oriented research approach.
钛媒体 · 31d ago

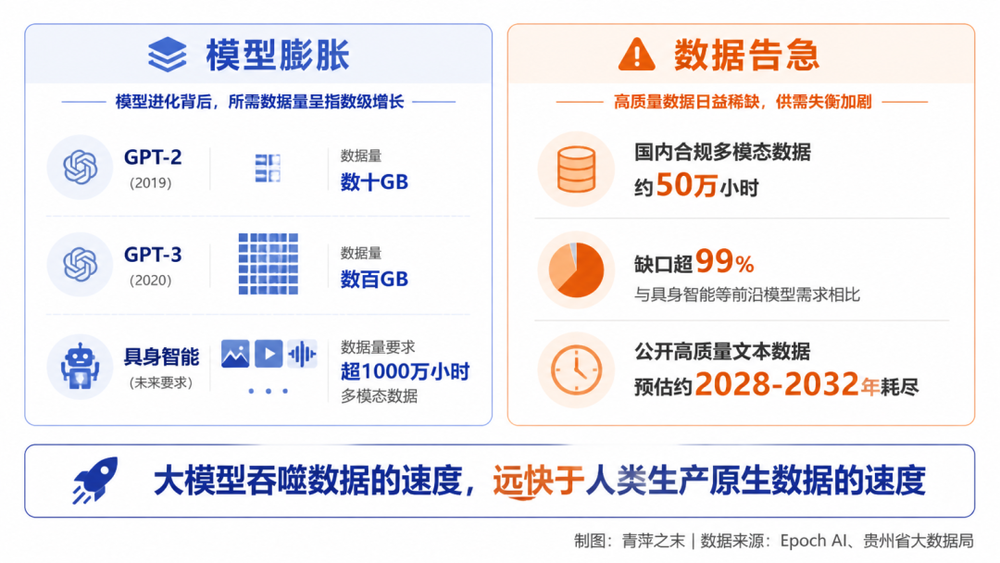
The article argues that high-quality, legally usable training data is becoming scarce as AI models scale and expand into multimodal applications. Publishers and content owners may gain new bargaining power, but copyright complexity, data engineering costs, synthetic data, and improved model efficiency could limit their pricing power.
虎嗅 · 33d ago

Hugging Face introduces LFM2.5-VL-3B as a vision-language model designed to deliver better and faster vision capabilities at the edge. The update highlights efficient deployment for applications that require local or low-latency multimodal inference.
Hugging Face Blog · 38d ago

紫东太初 has introduced the GMC core-set pruning method for multimodal models. The training-free, plug-and-play approach reportedly cuts token usage by 80% while preserving multimodal capabilities.
量子位 · 38d ago

Ming-Flash-Omni is presented as a unified multimodal foundation model. The article focuses on the key technologies and practical experiences behind building an end-to-end model that handles multiple modalities.
InfoQ中国 · 45d ago

OpenAI is testing a new real-time voice mode for its Codex model. This feature aims to assist users with daily tasks like managing Slack updates and ordering food, expanding its utility beyond pure coding.
TestingCatalog · 58d ago

Google has integrated sign language recognition into Gboard, signaling a strategic shift for the keyboard from a simple input tool to a multimodal AI platform. This move enhances accessibility and demonstrates the integration of complex computer vision tasks into everyday mobile interfaces.
钛媒体 · 61d ago

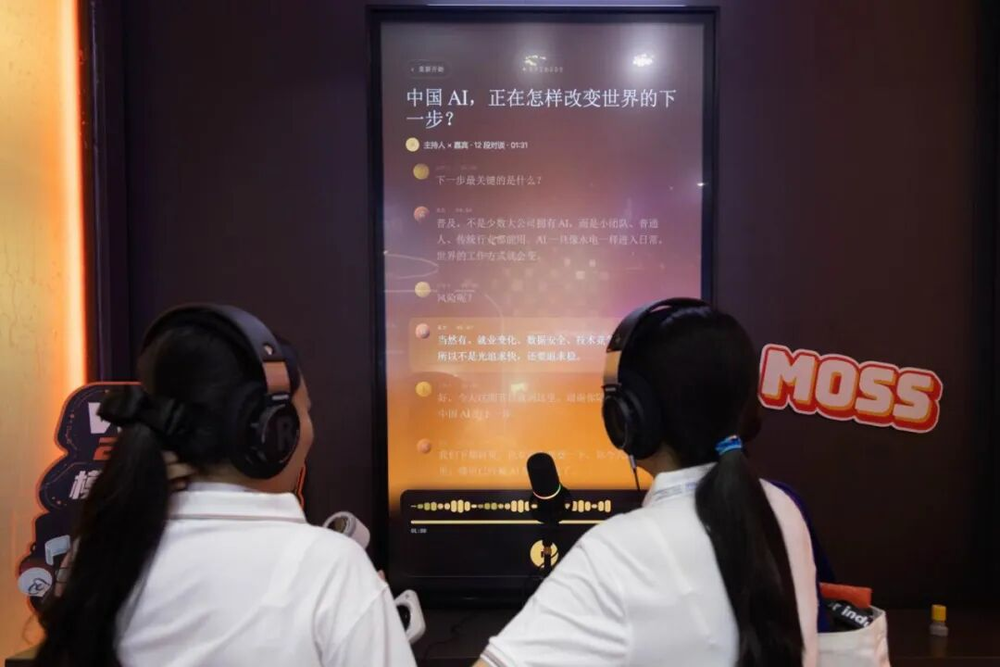
The MOSS team, creators of the early Chinese LLM, has founded Moss Intelligence to focus on 'Situational Intelligence' by prioritizing end-to-end voice interaction over text-only models. They are currently developing specialized models for voice transcription, video understanding, and TTS to enable more natural human-AI interaction.
虎嗅 · 63d ago

Google has integrated Gemini Omni and personal AI avatars into its Vids platform. These features allow paid users to generate and edit video content through natural language descriptions.
Digital Trends · 65d ago
The inaugural RTCA workshop at NeurIPS 2026 invites submissions on real-time multimodal conversational agents. It focuses on solving challenges in latency, turn-taking, and evaluation for live interactive systems.
Reddit r/MachineLearning · 65d ago

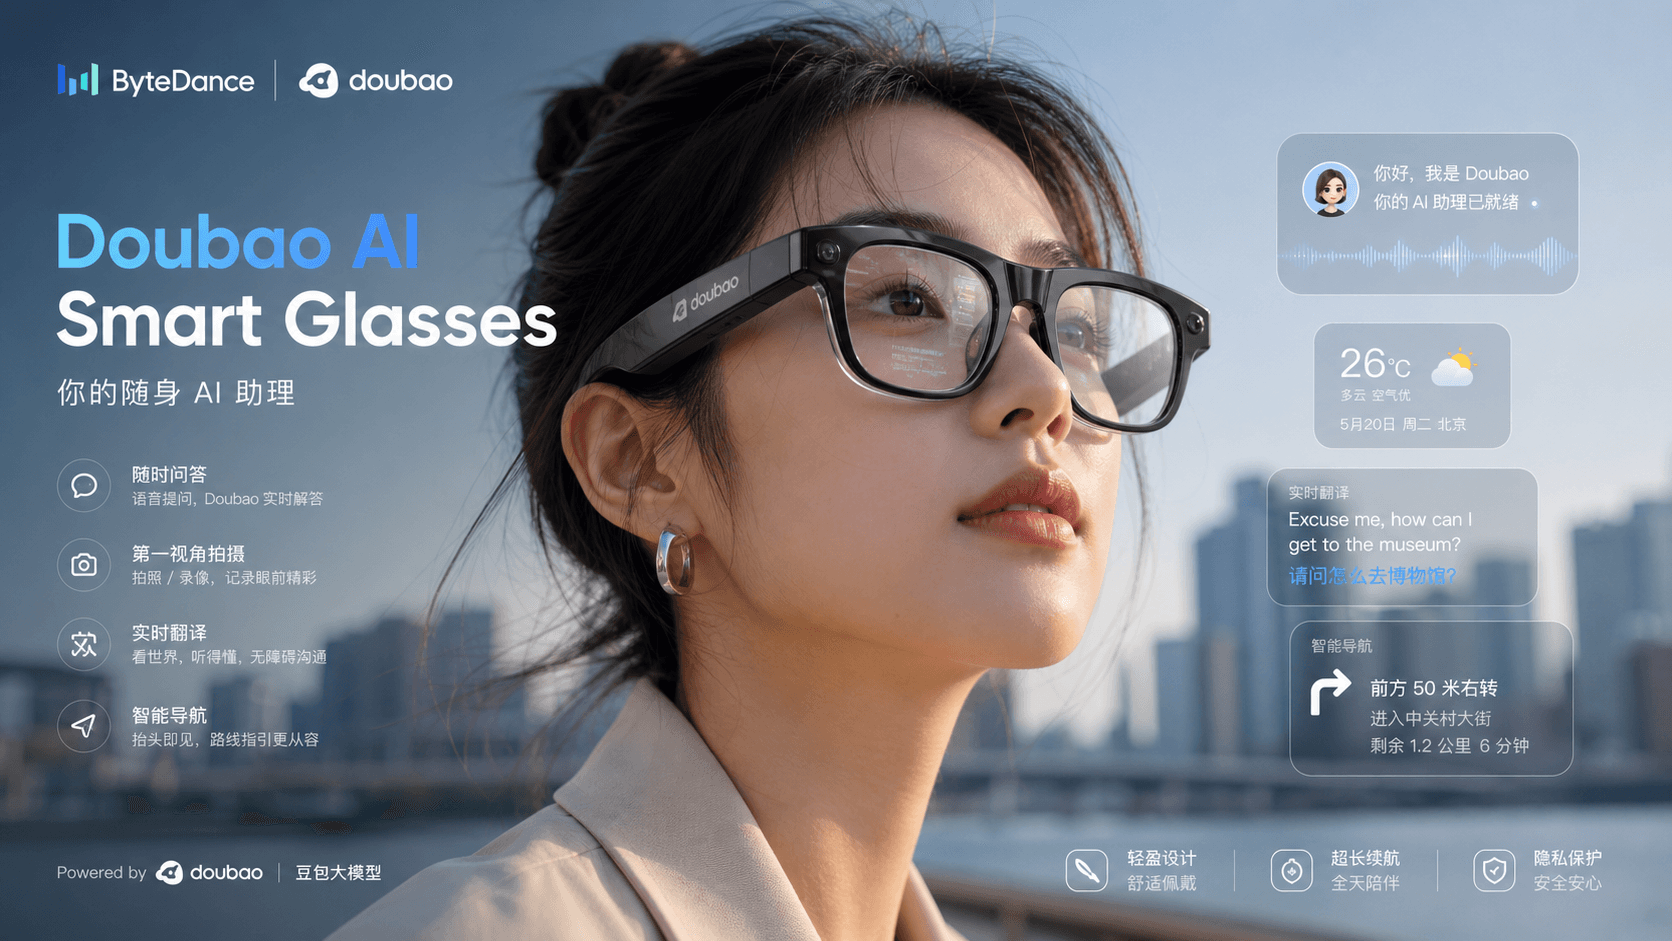
ByteDance has canceled its first-generation AI glasses to focus on a more competitive dual-model second generation. This move aims to challenge Meta's Ray-Ban smart glasses in a rapidly growing market.
Pandaily · 65d ago
Global AI content platform SeaArt has completed a B-round financing exceeding 100 million RMB. The funds will be directed toward multimodal model development, global market expansion, and AI vertical application incubation.
36氪 · 68d ago

YouTube has launched an AI-powered search feature in the US that allows users to find videos by describing specific situations, ideas, or activities. This conversational interface aims to improve content discovery by moving beyond simple keyword matching.
Digital Trends · 70d ago

ChatGPT's latest Live Voice update enables simultaneous listening, speaking, and online research capabilities. The experience offers a significantly more natural, human-like interaction for users.
ZDNet AI · 72d ago

Horus Hiero is a new open-source multimodal model built on Qwen 3.5, specifically designed for translating Ancient Egyptian hieroglyphs. It supports 150 languages and features a massive 512K context window.
Reddit r/LocalLLaMA · 73d ago

Tencent HY has recruited OpenAI research scientist Tian Yonglong to head its multimodal model development. He will report directly to chief AI scientist Yao Shunyu as part of a strategic talent acquisition push.
Pandaily · 73d ago

Meta has integrated its Muse image generation model with Instagram, allowing users to use social media profiles as a basis for AI-generated imagery. The model is also being deployed to power creative effects in Stories and image generation features within WhatsApp.
Engadget · 74d ago

openJiuwen has introduced Skill-Omni, a new multimodal paradigm that allows AI agents to learn from visual data rather than just text manuals. This shift enables agents to build a more intuitive and comprehensive experience library.
量子位 · 74d ago

The 'Electric F1' race in Shanghai features live commentary provided by Google's Gemini AI, marking a unique application of multimodal AI in sports broadcasting.
量子位 · 75d ago
AI video development is shifting focus from visual fidelity to functional intelligence. The next generation of avatars will prioritize the ability to see and listen, enabling more interactive and context-aware experiences.
The Next Web (TNW) · 79d ago

Om AI has released VLX, a streaming multimodal model specifically designed for physical world interaction. It is positioned as a breakthrough for edge-based AI applications.
量子位 · 80d ago

Zhipu AI's Tang Jie has initiated a global call for feedback regarding the development of the upcoming GLM-5.3 model. Early community response indicates a strong preference for enhanced visual capabilities.
量子位 · 81d ago

Huya has released VAM 1.0, a real-time multimodal digital human capable of 24/7 streaming. It requires only a single photo to generate a responsive avatar that can chat, sing, dance, and play games.
量子位 · 81d ago