Business
Starmer 'Appeasing' Big Tech on Regulation
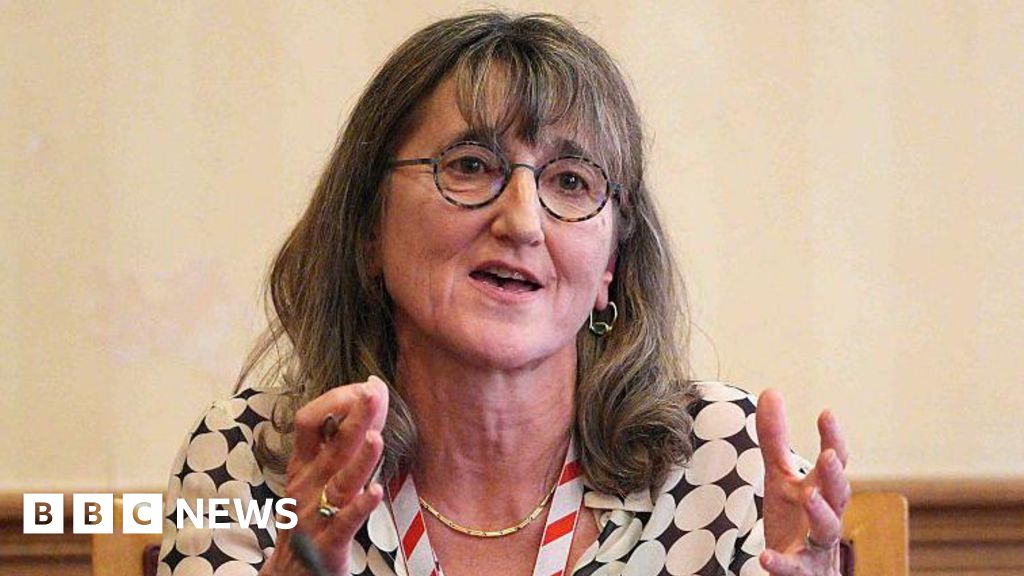
Online safety campaigner Baroness Kidron accuses UK PM Starmer of appeasing big tech firms. She tells BBC the PM has been 'late to the party' in regulating social media.
BBC Technology · 208d ago
Every story we have kept, newest first.
Looking for the daily editions? → Past editions
Page 1324 of 1372
Online safety campaigner Baroness Kidron accuses UK PM Starmer of appeasing big tech firms. She tells BBC the PM has been 'late to the party' in regulating social media.
BBC Technology · 208d ago
UK charity Mind launches a year-long inquiry into AI's impact on mental health after a Guardian investigation revealed Google AI Overviews providing 'very dangerous' advice. The commission will assess risks and necessary safeguards as AI affects millions worldwide.
The Guardian Technology · 208d ago
Robots dazzled at China’s Spring Festival gala with comedy skits, Mandarin pop dancing, and martial arts-like bounces. Investors boosted shares in robotics firms on Friday, even as the broader market declined.
Bloomberg Technology · 208d ago
Gartner forecasts semantic layers as critical AI infrastructure by 2030, slashing rework costs by 40% for adopters. Palantir's Ontology exemplifies this by translating raw data into business logic, enabling low-hallucination AI agents.
虎嗅 · 208d ago

Two former Google engineers and one spouse face US federal charges for stealing trade secrets on the Tensor processor used in Pixel phones. The Iranian nationals are hit with 14 felony counts including conspiracy, theft of trade secrets, and evidence destruction.
cnBeta (Full RSS) · 208d ago

Google's Pomelli Photoshoot is an AI tool that transforms simple smartphone photos into studio-quality product images. It is now available in the US, Canada, Australia, and New Zealand.
Digital Trends · 208d ago

Counterpoint Research reports Apple leads with 25% share of global active smartphones by end-2025. Apple dominates profits, capturing over 90% of industry earnings despite not topping sales volumes.
cnBeta (Full RSS) · 208d ago

Reddit user reports iPhone Air suffering hardware failure in Apple's self-developed baseband, causing complete loss of cellular signal. Device was protected in case with no drop history.
cnBeta (Full RSS) · 208d ago
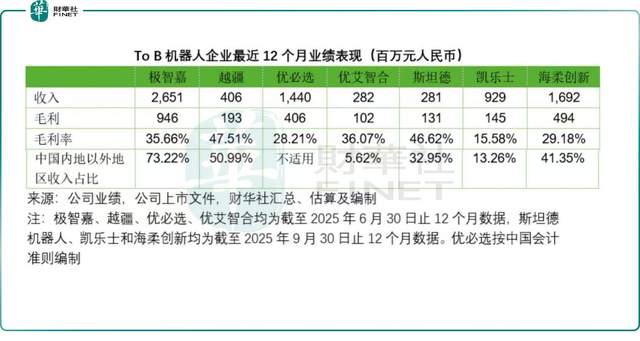
Robot industry remains in investment-heavy phase based on 2025 H1 financials. Differentiation among companies is increasingly evident.
钛媒体 · 208d ago

OpenAI CEO Sam Altman told CNBC that Chinese tech firms advance rapidly across the full tech stack. He noted impressive speed in AI and other fields, nearing frontiers in some areas while lagging in others.
cnBeta (Full RSS) · 208d ago
Snyk's CEO is stepping down to enable the company to hire a leader with greater AI expertise. The code review platform seeks an 'innovative and disruptive visionary' skilled in AI to navigate the AI era.
The Register - AI/ML · 208d ago
Sentinel is an open-source, fast LLM gateway in Rust offering a single OpenAI-compatible endpoint that routes to multiple providers like OpenAI and Anthropic. It includes retries with exponential backoff, exact-match caching, PII redaction, SQLite logging, cost tracking, and a dashboard.
Reddit r/MachineLearning · 208d ago

SourceBench introduces a benchmark to evaluate the quality of web sources cited by LLMs across 100 real-world queries in various intents. It employs an eight-metric framework assessing content relevance, factual accuracy, objectivity, freshness, authority, and clarity, backed by a human-labeled dataset and calibrated LLM evaluator.
ArXiv AI · 208d ago
A new arXiv paper shows simple baselines match or outperform complex code evolution techniques using LLMs across math bounds, agentic scaffolds, and ML competitions. It identifies key issues like poor search space design and high evaluation variance.
ArXiv AI · 208d ago
Raspberry Pi Foundation published a guide for running OpenClaw on Pi 5, featuring a wedding photo booth demo. Adafruit covered it, and Medium bloggers are documenting setups.
OpenClaw.report · 208d ago
This paper introduces a unified order-oriented framework for scoring hesitant fuzzy sets, addressing limitations in traditional methods. It analyzes classical orders, proving they lack lattice structures, while symmetric orders meet key normative criteria like strong monotonicity.
ArXiv AI · 208d ago
Node Learning is a decentralized paradigm where edge nodes learn continuously from local data and exchange knowledge opportunistically via peer interactions. It propagates learning through overlap and diffusion, avoiding global synchronization or central aggregation.
ArXiv AI · 208d ago
NeuDiff Agent is a governed AI workflow for TOPAZ at Spallation Neutron Source, automating single-crystal neutron crystallography from data reduction to validated CIF output. It restricts actions to allowlisted tools, enforces fail-closed verification gates, and captures full provenance.
ArXiv AI · 208d ago
Narrow fine-tuning on harmful datasets erodes safety alignment in vision-language models, causing misalignment that generalizes across unrelated tasks and modalities. Experiments on Gemma3-4B reveal misalignment scales with LoRA rank and is worse in multimodal evaluation (70.71%) than text-only (41.19%).
ArXiv AI · 208d ago
MobCache is a mobility-aware cache framework that enables scalable LLM-based human mobility simulations by reusing reconstructible reasoning caches. It encodes reasoning steps as latent embeddings for recombination and uses a lightweight decoder trained via mobility-constrained distillation.
ArXiv AI · 208d ago
Researchers leverage LLMs, RAG, and GraphRAG to generate Design Structure Matrices (DSMs) for cyber-physical systems. Methods tested on power screwdriver and CubeSat use cases, assessing component relationships and identification.
ArXiv AI · 208d ago
LLM-WikiRace is a new benchmark evaluating LLMs on long-term planning and reasoning by navigating Wikipedia hyperlinks from source to target pages. Frontier models like Gemini-3, GPT-5, and Claude Opus 4.5 excel on easy levels but drop to 23% success on hard ones.
ArXiv AI · 208d ago
IndicJR introduces a judge-free benchmark evaluating jailbreak robustness in 12 South Asian languages with 45,216 prompts across JSON and Free tracks. It uncovers that contracts boost refusals but fail against jailbreaks, English attacks transfer effectively to Indic, and orthography like romanization weakens defenses.
ArXiv AI · 208d ago
GUI-Owl-1.5 introduces multi-size native GUI agent models (2B-235B) supporting desktop, mobile, browser platforms for cloud-edge collaboration. It sets SOTA on 20+ benchmarks like 56.5 on OSWorld, 71.6 on AndroidWorld, and 80.3 on ScreenSpotPro.
ArXiv AI · 208d ago
Researchers introduce the GAP benchmark to evaluate divergence between text-level and tool-call safety in LLM agents. Testing six frontier models across six domains reveals text refusals do not prevent harmful tool calls, with 219 persistent cases even under safety prompts.
ArXiv AI · 208d ago
Adaptive systems reuse fixed internal states across contexts due to resource limits, leading to inevitable contextuality in classical probabilistic models. The paper proves an irreducible information-theoretic cost for reproducing contextual statistics.
ArXiv AI · 208d ago
AIdentifyAGE ontology provides a standardized framework for forensic dental age assessment, supporting manual and AI-assisted workflows. It integrates clinical, forensic, legal data, radiographic imaging, and ML methods for interoperability and transparency.
ArXiv AI · 208d ago
Researchers prove S(n) ≤ ⌈4n/5⌉ for hypercube edge slicing, beating 1971's ⌈5n/6⌉ bound. They used CPro1, an LLM-powered tool, to construct 8 hyperplanes slicing Q_{10}.
ArXiv AI · 208d ago
A systematic ArXiv study analyzes saturation across 60 LLM benchmarks from major developers. Nearly half show saturation, worsening with age, and hiding test data offers no protection.
ArXiv AI · 208d ago