HiDream Launches HiDream-O1-Embodied World Model
HiDream.ai has announced HiDream-O1-Embodied, an embodied world model. The release represents the company’s effort to complete a native multimodal technology strategy loop.
量子位 · 12d ago
Models that see, hear and speak are replacing text-only systems. Coverage of vision-language models, native audio and video understanding.
354 articles
HiDream.ai has announced HiDream-O1-Embodied, an embodied world model. The release represents the company’s effort to complete a native multimodal technology strategy loop.
量子位 · 12d ago
少數派報導了多項 AI 產品更新,包括 Google 發布 Gemini 3.8 Flash、World Labs 發布多模態世界模型 Atlas,以及 Alibaba 推出 Qwen3.8-Max-0902。文章同時提及理想新一代 MEGA 等其他產品動態。
少数派 · 16d ago

Google has quietly launched Gemini 3.8 Flash, an upgraded model based on Gemini 3.7 Flash for software engineering, agent tasks, and complex knowledge workflows. It targets developers, enterprises, and large-scale production deployments that need a balance of quality, cost, and latency.
极客公园 · 16d ago

Google launched Gemini 3.8 Flash for agentic tasks, software development, and multi-step reasoning, alongside Flash Cyber for vulnerability discovery and remediation. The models are available through Gemini Enterprise and developer tools, with pricing starting at $0.75 per million input tokens.
VentureBeat · 16d ago

Li Fei-Fei’s team has reportedly launched Atlas, described as the world’s first multimodal world model. Instead of only understanding text, Atlas aims to understand spatial environments from a small number of photographs, potentially replacing hundreds of camera viewpoints.
Ifanr (爱范儿) · 17d ago

Vercel has made Google’s Gemini 3.8 Flash available through AI Gateway, offering a 1M-token context window and multimodal input support. The model is 50% off through December 31 and improves software engineering, agent workflows, and multi-step reasoning at the previous model’s speed and cost.
Vercel News · 17d ago

智谱开源了原生多模态模型 GLM-5.3-Flash,开发者可关注其在文本与视觉任务中的应用潜力。该消息收录于少数派的科技新闻汇总,文中同时提及 Perplexity Portable Computer 与 BenQ Creative Pro PV50 系列显示器。
少数派 · 22d ago

Tencent’s WeChat Vision team has open-sourced WeMM-Embedding, a family of models for matching text, images, videos and other content types. The models are already deployed across WeChat services, with 2B, 4B and 9B versions included in the release.
TechNode · 23d ago
China’s Z.ai has released GLM-5.3-Flash under the MIT license. The multimodal model, previously evaluated anonymously as “Ox Alpha,” claims near-Claude Opus 4.8 performance at lower cost on clusters of Chinese-made AI chips.
ITmedia AI+ (日本) · 23d ago

Alibaba’s Qwen team plans to open-source Qwen3.8-Flash-Next and an FP8 version on Aug. 26.
TechNode · 24d ago

Vercel has added Z.ai’s GLM 5.3 Flash to AI Gateway, enabling developers to access the multimodal model through a unified API. The model supports text and vision input, function calling, structured output, streaming, and a 1M-token context window.
Vercel News · 24d ago

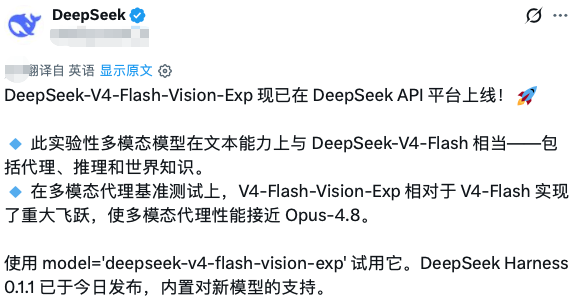
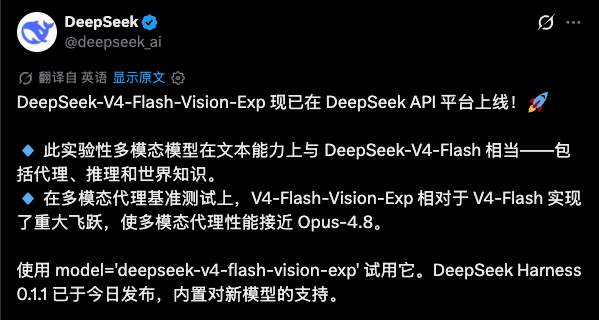
DeepSeek has added native image input to V4 Flash through the experimental Vision-Exp model, enabling image understanding, visual agents, and screenshot-based coding tasks. Testing shows strong scene description and basic webpage reconstruction, but inconsistent identity recognition, high token use, and experimental reliability remain concerns.
虎嗅 · 25d ago

HiDream.ai launched HiDream-O1-World, an interactive world model built on its native multimodal UiT architecture. The model accepts text, images, and interactive controls, targeting embodied-AI simulation, interactive entertainment, and 3D scene generation.
雷峰网 · 26d ago

BOCOM International’s analysis places Moonshot AI’s Kimi K3 on the cost-capability Pareto frontier. Its large context window and multimodal design reportedly deliver performance close to leading closed models at substantially lower per-task cost.
Pandaily · 26d ago

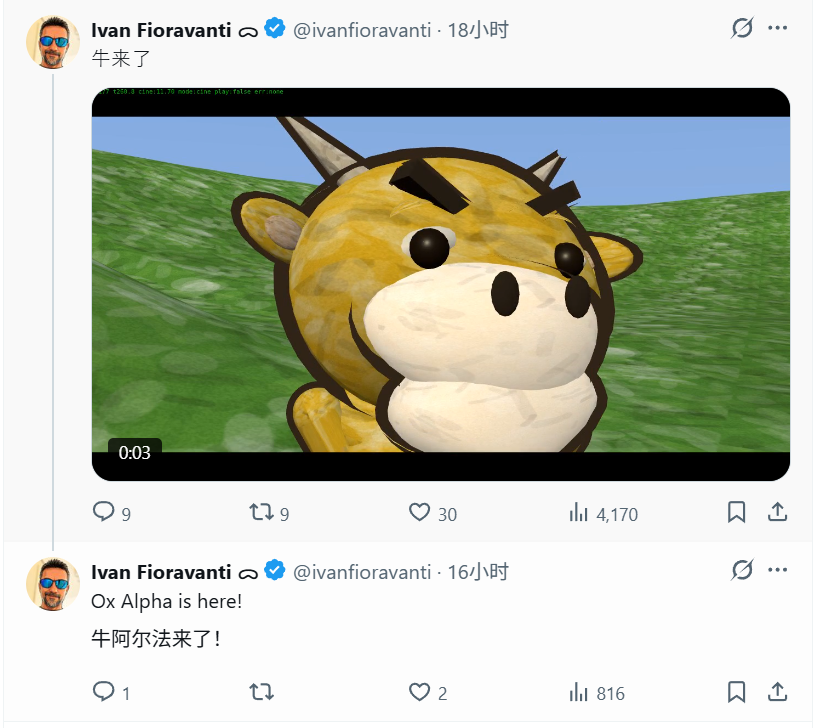
Ox Alpha is an anonymous model available through OpenRouter and OpenCode, offering a 1M-token context window, multimodal inputs, tool use, and free access. Early tests show strong reasoning and coding performance, but its developer, parameters, training data, and benchmark standing remain unverified.
虎嗅 · 28d ago

DeepSeek has released DeepSeek-V4-Flash-Vision-Exp, its latest model focused on visual capabilities. The announcement marks the company’s entry into multimodal model updates after an extended period of anticipation.
cnBeta (Full RSS) · 28d ago

DeepSeek has launched the V4-Flash-Vision-Exp model on its API platform, enabling image inputs alongside text for visual analysis tasks. The company says its multimodal agent performance has improved substantially and approaches Opus-4.8 on visual-agent benchmarks.
极客公园 · 28d ago

MiniMax H3 delivers high-quality video generation and editing, supporting up to 2K output at roughly RMB 0.8 per second. Shortly after H3 launched, MiniMax introduced the MiniMax Design beta, an agent-based workspace that decomposes creative tasks and orchestrates multiple AI agents for end-to-end video production.
极客公园 · 29d ago

Xiaohongshu has released the dots3-note preview, an open-weight MoE model with 280B total and 16B activated parameters. The model supports a 512K context window plus text, vision, and voice understanding, and is available under Apache 2.0.
Pandaily · 29d ago

SenseTime has open-sourced SenseNova U1.5 Lite, an 8-billion-parameter multimodal model combining visual understanding, image generation, and editing. It supports native 4K image output and targets tasks involving subjects, counts, spatial relationships, text, layouts, and visual styles.
TechNode · 29d ago

Mistral AI released Shieldstral, a 3B-parameter adaptive multimodal safety classifier for text, images, and mixed text-image inputs. It converts moderation into natural-language rule matching and reportedly approaches or exceeds larger models on several safety benchmarks.
雷峰网 · 33d ago

智象未来 launched HiDream-O1-World, a native multimodal interactive world model that supports text, image, and interactive inputs for world generation, navigation, and editing. Built on its upgraded UiT architecture, the model ranked first on WBench’s Navi leaderboard with an average score of 80.9.
雷峰网 · 33d ago

A new world model is reported to generate 24FPS visuals and 48kHz stereo audio in real time. The project is expected to become fully open source soon.
量子位 · 33d ago

Microsoft has launched MAI-Code-1.1-Flash, an upgraded coding model for GitHub Copilot with stronger benchmark performance, 25% faster token generation, and 25% lower token usage for equivalent tasks. Its pricing has been reduced to one quarter of the original model, and it adds native image understanding.
IT之家 · 38d ago

Grok 4.6 from xAI is now available through Vercel AI Gateway, with a 500K-token context window and text and image input support. Developers can select reasoning levels from low to xhigh, with high as the default, and access the model through the AI SDK or coding agents.
Vercel News · 38d ago

MiniMax H3 now offers open weights and combines text, image, video, and audio as context in one workflow. It can generate native stereo audio for up to 15 seconds at 2K, while the 768p Base model reportedly runs on consumer GPUs in minutes.
Pandaily · 40d ago
Meta has introduced Muse Glimmer, an open-source AI system designed to run locally. The product is described as agentic and multimodal, indicating support for autonomous task execution across multiple input and output modalities.
Hugging Face Blog · 40d ago

ByteDance has released SeedRealtime, an audio-video full-duplex foundation model designed for more natural real-time interaction. The same roundup also reports JD.com’s open-source JoyAI-Video-Edit model, which supports real-time interactive video editing.
钛媒体 · 44d ago

ByteDance has launched SeedRealtime, a full-duplex AI model designed for continuous conversations. It unifies audio, video, and text while supporting proactive responses and more natural conversational timing.
TestingCatalog · 45d ago
Alibaba has officially launched Qwen-Image-3.0, the third generation of its image generation foundation model. The model features enhanced capabilities including 4.5k token input support, precise 10px text rendering, and native support for 12 languages.
36氪 · 60d ago