OpenAI and Broadcom Partner for Custom LLM Inference Chips
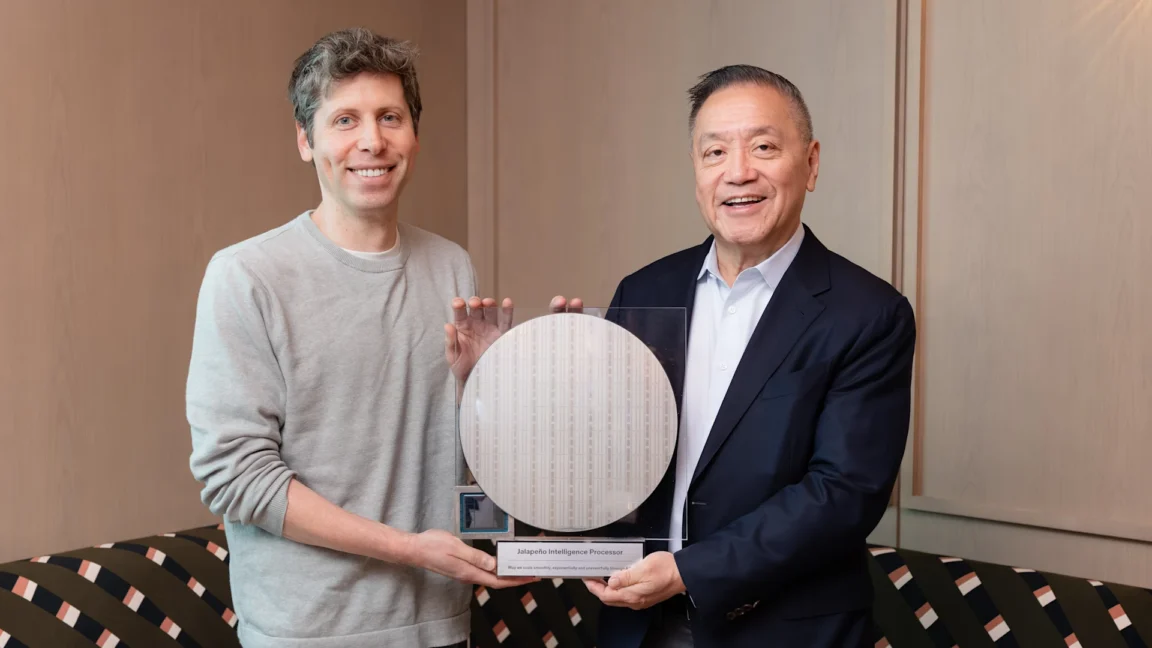
OpenAI moves to custom silicon with Broadcom to solve the bottleneck of large-scale LLM inference.
30-Second TL;DR
What Changed
OpenAI and Broadcom are co-developing custom silicon for LLM inference.
Why It Matters
This partnership signals a shift toward vertical integration in AI infrastructure, potentially lowering inference costs and increasing performance for OpenAI's models.
What To Do Next
Monitor future OpenAI API performance benchmarks as custom silicon integration may lead to lower latency and costs for developers.
Key Points
- •OpenAI and Broadcom are co-developing custom silicon for LLM inference.
- •The partnership focuses on scaling infrastructure to meet high demand.
- •Custom chips aim to improve efficiency and performance for AI workloads.
Deep Insight
AI-generated analysis for this event — not the original article.
Enhanced Key Takeaways
- •The partnership leverages Broadcom's expertise in ASIC design and high-speed interconnects, specifically targeting the reduction of latency in massive transformer-based model inference.
- •OpenAI is reportedly utilizing TSMC's advanced packaging technologies, such as CoWoS (Chip-on-Wafer-on-Substrate), to integrate high-bandwidth memory (HBM) directly with the custom silicon.
- •This initiative is part of OpenAI's broader 'sovereign silicon' strategy, aimed at diversifying its supply chain beyond NVIDIA's GPU ecosystem to mitigate potential hardware shortages.
- •The custom chips are expected to prioritize energy efficiency per token, addressing the massive power consumption challenges associated with running models like GPT-5 or its successors at scale.
- •Reports indicate that OpenAI has been actively recruiting former Google TPU (Tensor Processing Unit) engineers to lead the architectural design of these custom inference accelerators.
Competitor Analysis
- OpenAI/Broadcom (Custom)
- Inference Efficiency
- NVIDIA (Blackwell/Rubin)
- General Purpose AI
- Google (TPU v6)
- Cloud TPU Scaling
- Amazon (Inferentia)
- Cost-Optimized Inference
- OpenAI/Broadcom (Custom)
- ASIC (Inference-Specific)
- NVIDIA (Blackwell/Rubin)
- GPU (General Purpose)
- Google (TPU v6)
- ASIC (Tensor-Optimized)
- Amazon (Inferentia)
- ASIC (Inference-Optimized)
- OpenAI/Broadcom (Custom)
- Proprietary/Closed
- NVIDIA (Blackwell/Rubin)
- CUDA (Dominant)
- Google (TPU v6)
- JAX/TensorFlow
- Amazon (Inferentia)
- AWS/Neuron
| Feature | OpenAI/Broadcom (Custom) | NVIDIA (Blackwell/Rubin) | Google (TPU v6) | Amazon (Inferentia) |
|---|---|---|---|---|
| Primary Focus | Inference Efficiency | General Purpose AI | Cloud TPU Scaling | Cost-Optimized Inference |
| Architecture | ASIC (Inference-Specific) | GPU (General Purpose) | ASIC (Tensor-Optimized) | ASIC (Inference-Optimized) |
| Ecosystem | Proprietary/Closed | CUDA (Dominant) | JAX/TensorFlow | AWS/Neuron |
Technical Deep Dive
- Architecture: Likely a domain-specific ASIC optimized for matrix multiplication and attention mechanism acceleration.
- Interconnect: Integration of Broadcom's high-speed SerDes (Serializer/Deserializer) technology to facilitate multi-chip communication.
- Memory: Utilization of HBM3e or HBM4 to provide the massive memory bandwidth required for large LLM parameter weights.
- Process Node: Expected to be manufactured on TSMC's 3nm or 2nm process nodes for maximum transistor density and power efficiency.
Future ImplicationsAI analysis grounded in cited sources
Timeline
- 2023-10OpenAI begins internal exploration of custom silicon acquisition and design strategies.
- 2024-04OpenAI forms a dedicated hardware unit to oversee custom chip development and supply chain diversification.
- 2024-09Initial reports emerge regarding OpenAI's high-level discussions with Broadcom for ASIC development.
- 2025-02OpenAI formalizes the partnership with Broadcom to begin the tape-out process for inference-optimized silicon.
- 2026-05First prototypes of the custom inference chips are delivered for internal validation and testing.
Event Coverage
Weekly AI Recap
Read this week's curated digest of top AI events →
Related Updates
AI-curated news aggregator. All content rights belong to original publishers.
Original source: Ars Technica AI ↗
This is a summary, not the original. Read the source, or get the weekly briefing.
The weekly digest
One email a week. Unsubscribe anytime.