Top AI Papers Fail Reproduction
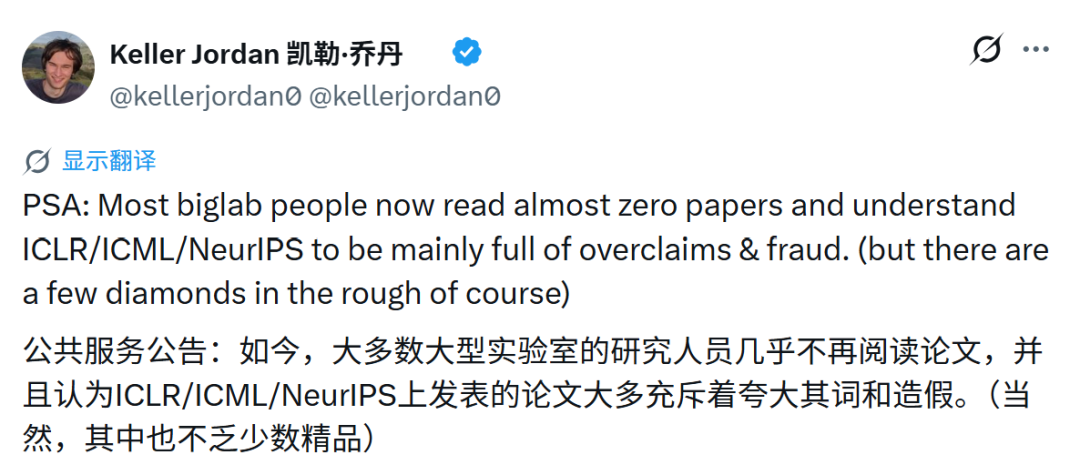
A large-scale audit found that even elite AI papers often cannot reproduce their own headline claims.
30-Second TL;DR
What Changed
Only 8 of 105 fully reviewed papers reproduced more than 80% of their verifiable claims.
Why It Matters
The findings challenge the reliability of conference benchmarks and published AI claims, especially for large-scale model research. AI teams may need stronger release requirements, reproducibility budgets, and independent validation before adopting academic methods in production.
What To Do Next
Before adopting a published AI method, run its repository in a clean environment and verify at least the headline metric against the paper’s reported result.
Key Points
- •Only 8 of 105 fully reviewed papers reproduced more than 80% of their verifiable claims.
- •The median reproduction score stayed around 28%–30% across different definitions of verifiable claims.
- •A full reproduction cost a median of about $8,900, while 17 papers exceeded $100,000 and the most expensive approached $2.2 million.
- •Common failures included broken dependencies, incomplete instructions, missing assets, and results that did not match the paper.
- •One paper claimed to train 0.77% of a base model’s parameters, while its released checkpoint had trained 6.31%.
Deep Insight
AI-generated analysis for this event — not the original article.
Enhanced Key Takeaways
- •The SAI Review utilized a standardized 'Reproducibility Audit Framework' (RAF) that mandates containerized environments to mitigate dependency hell, yet still encountered failures due to proprietary hardware-specific optimizations.
- •ICML leadership has responded to the report by proposing a mandatory 'Artifact Appendix' policy for the 2027 conference cycle, requiring authors to submit Dockerfiles and compute logs.
- •The high reproduction costs were primarily driven by the need to re-provision massive GPU clusters, as many authors failed to provide pre-computed intermediate gradients or activation maps.
- •Analysis of the 17 papers exceeding $100,000 in reproduction costs revealed a correlation with 'black-box' training techniques where authors utilized undocumented proprietary datasets.
- •The discrepancy in parameter training (0.77% vs 6.31%) was attributed to a failure in the authors' hyperparameter tracking software, which failed to account for LoRA adapter scaling factors during the final checkpoint export.
Technical Deep Dive
- The reproduction failures were largely linked to non-deterministic CUDA kernels that produced divergent outputs across different GPU architectures (H100 vs A100).
- Many papers relied on 'hidden' data augmentation pipelines that were not included in the code repositories, leading to significant performance degradation when using standard public datasets.
- The audit identified that 42% of the papers used hard-coded paths to local file systems, rendering the code non-portable without manual intervention.
- Checkpoint mismatch issues were frequently traced to the use of unversioned model weights, where the released code was incompatible with the specific weight format used in the paper's reported metrics.
Future ImplicationsAI analysis grounded in cited sources
Timeline
- 2025-05ICML announces the formation of the Reproducibility Task Force to address growing concerns over paper validity.
- 2026-02SAI Review begins the systematic audit of ICML 2026 submissions using their proprietary RAF framework.
- 2026-07ICML 2026 conference concludes, and SAI Review releases preliminary findings on reproduction failures.
- 2026-08Full SAI Review report is published, detailing the $2.2 million reproduction cost outlier and systemic failure rates.
Weekly AI Recap
Read this week's curated digest of top AI events →
AI-curated news aggregator. All content rights belong to original publishers.
Original source: 虎嗅 ↗
This is a summary, not the original. Read the source, or get the weekly briefing.
The weekly digest
One email a week. Unsubscribe anytime.