How DeepSeek Became a ChatGPT Rival
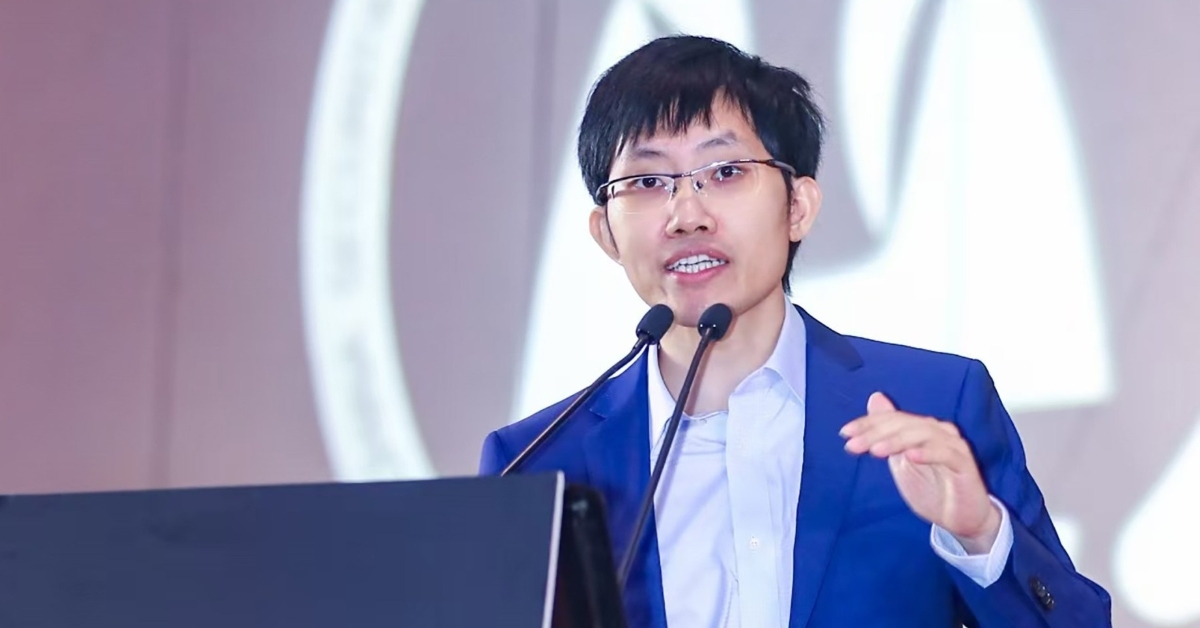
Learn how a three-year-old AI company became a ChatGPT rival without relying on overtime.
30-Second TL;DR
What Changed
DeepSeek reached major-rival status in approximately three years.
Why It Matters
DeepSeek's trajectory shows how quickly an AI company can gain strategic relevance in the competitive LLM market. Its reported work model may also challenge assumptions that frontier AI progress requires sustained employee overtime.
What To Do Next
Evaluate DeepSeek models alongside your current LLM on one representative workload, measuring quality, latency, and operating cost.
Key Points
- •DeepSeek reached major-rival status in approximately three years.
- •The company is presented as operating without employee overtime.
- •The article focuses on the young founder's management and execution capabilities.
Deep Insight
AI-generated analysis for this event — not the original article.
Enhanced Key Takeaways
- •DeepSeek is backed by High-Flyer Quant, a prominent Chinese quantitative hedge fund, which provided the necessary computational infrastructure and capital.
- •The company emphasizes 'efficiency-first' engineering, utilizing custom-optimized kernels and sparse attention mechanisms to drastically reduce training costs compared to Western counterparts.
- •DeepSeek has adopted an open-weights strategy for many of its models, significantly accelerating its adoption among the global developer community and research institutions.
- •The organization maintains a lean research team, often cited as having fewer than 100 employees, which contrasts sharply with the thousands of staff at major US AI labs.
- •DeepSeek's technical strategy focuses heavily on Mixture-of-Experts (MoE) architectures to achieve high performance while maintaining lower inference latency and power consumption.
Competitor Analysis
- DeepSeek (V3/R1)
- Mixture-of-Experts (MoE)
- OpenAI (GPT-4o)
- Dense/Hybrid
- Anthropic (Claude 3.5)
- Dense
- DeepSeek (V3/R1)
- Highly aggressive/Low cost
- OpenAI (GPT-4o)
- Premium
- Anthropic (Claude 3.5)
- Premium
- DeepSeek (V3/R1)
- Open Weights
- OpenAI (GPT-4o)
- Closed
- Anthropic (Claude 3.5)
- Closed
- DeepSeek (V3/R1)
- Training/Inference Efficiency
- OpenAI (GPT-4o)
- Ecosystem/Integration
- Anthropic (Claude 3.5)
- Reasoning/Safety
| Feature | DeepSeek (V3/R1) | OpenAI (GPT-4o) | Anthropic (Claude 3.5) |
|---|---|---|---|
| Architecture | Mixture-of-Experts (MoE) | Dense/Hybrid | Dense |
| Pricing | Highly aggressive/Low cost | Premium | Premium |
| Openness | Open Weights | Closed | Closed |
| Primary Edge | Training/Inference Efficiency | Ecosystem/Integration | Reasoning/Safety |
Technical Deep Dive
- Utilizes Multi-head Latent Attention (MLA) to reduce KV cache memory usage during inference.
- Implements DeepSeekMoE, a fine-grained expert architecture that improves knowledge specialization and reduces computational overhead.
- Employs advanced reinforcement learning techniques for reasoning models, similar to chain-of-thought optimization.
- Optimizes training throughput via custom communication libraries designed to handle large-scale GPU clusters with high efficiency.
Future ImplicationsAI analysis grounded in cited sources
Timeline
- 2023-07DeepSeek is founded with backing from High-Flyer Quant.
- 2024-01Release of DeepSeek-LLM, marking their entry into the competitive large language model space.
- 2024-05Launch of DeepSeek-V2, introducing the innovative DeepSeekMoE architecture.
- 2024-12Release of DeepSeek-V3, demonstrating state-of-the-art performance at a fraction of the training cost.
- 2025-01Release of DeepSeek-R1, a reasoning-focused model that gained significant global attention.
Weekly AI Recap
Read this week's curated digest of top AI events →
Related Updates
AI-curated news aggregator. All content rights belong to original publishers.
Original source: ITmedia AI+ (日本) ↗
This is a summary, not the original. Read the source, or get the weekly briefing.
The weekly digest
One email a week. Unsubscribe anytime.