China's Lingsheng Supercomputer Breaks 2 Exaflops Barrier
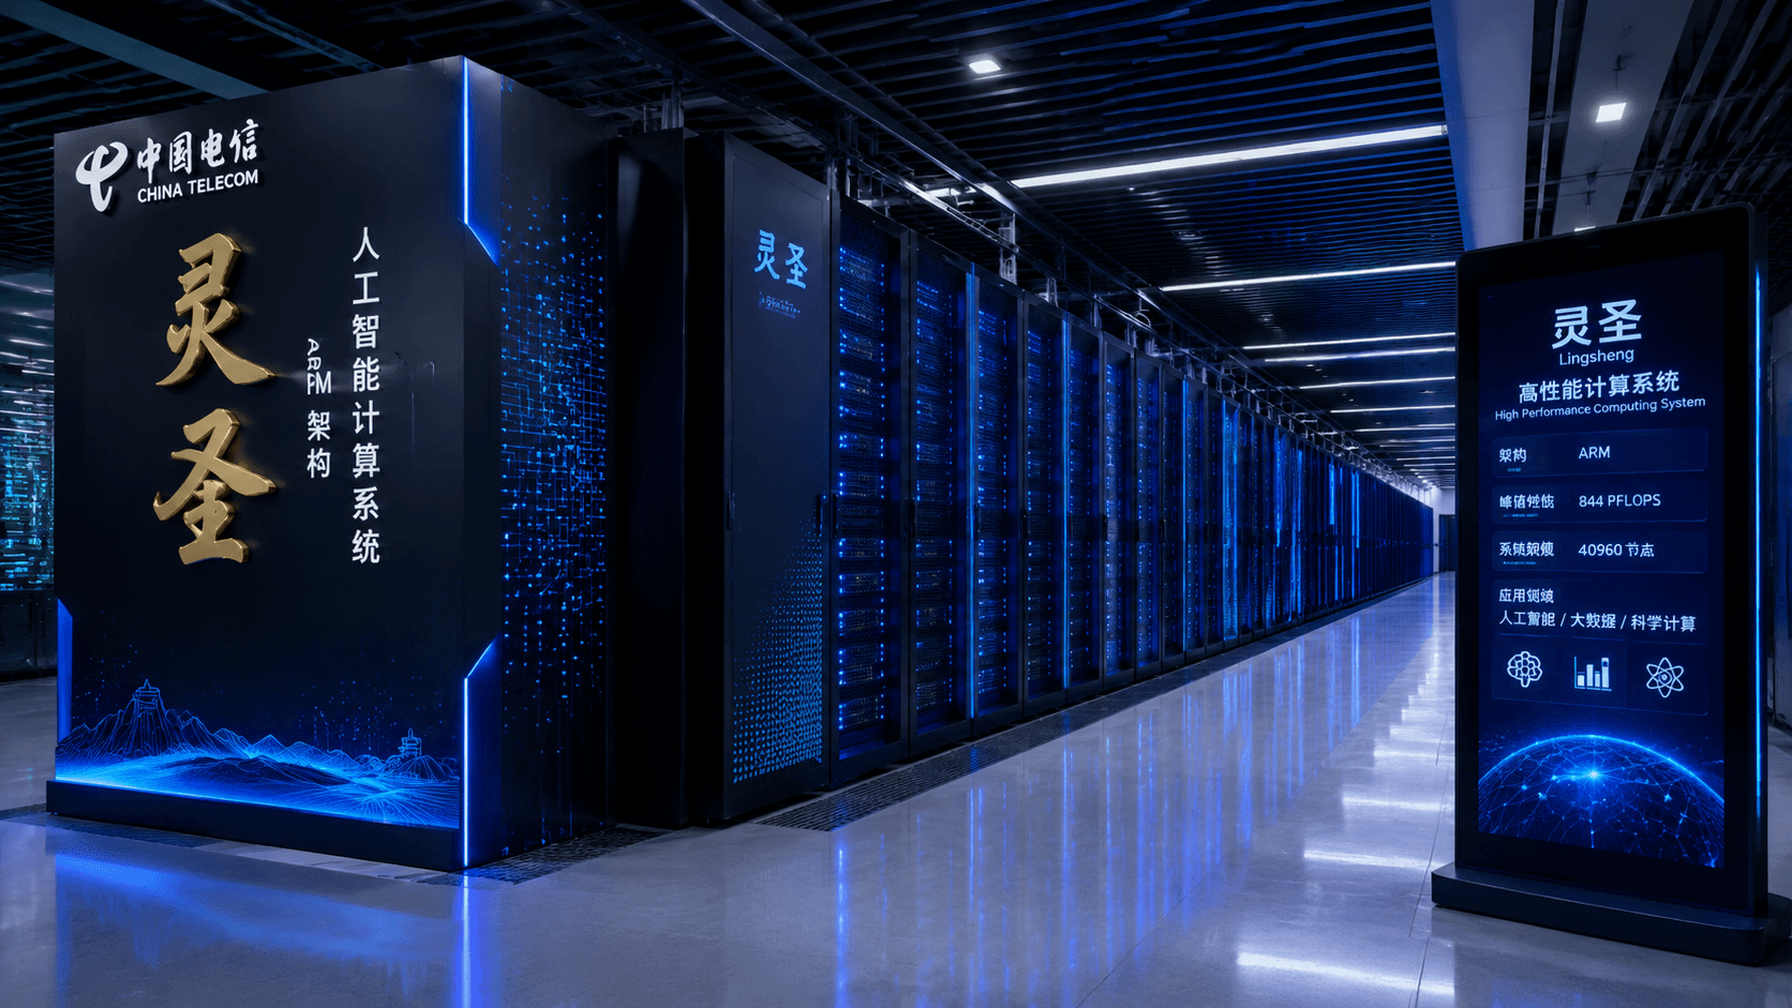
Exascale computing breakthroughs directly influence the future of large-scale AI model training and research.
30-Second TL;DR
What Changed
Lingsheng system exceeds 2 exaflops in computational capacity.
Why It Matters
Increased exascale computing power will accelerate AI model training and scientific simulations. It underscores the intensifying global race for high-performance compute resources.
What To Do Next
Evaluate how exascale-ready infrastructure impacts the training time for large-scale distributed AI models.
Key Points
- •Lingsheng system exceeds 2 exaflops in computational capacity.
- •The achievement signals a significant leap in high-performance computing (HPC) infrastructure.
- •This marks a return to global leadership in supercomputing rankings for China.
Deep Insight
AI-generated analysis for this event — not the original article.
Enhanced Key Takeaways
- •The Lingsheng system utilizes a novel heterogeneous architecture combining custom-designed RISC-V based accelerators with high-bandwidth memory (HBM3e) to achieve its power efficiency targets.
- •Development of the Lingsheng supercomputer was spearheaded by the National Supercomputing Center in Jinan, leveraging domestic semiconductor supply chains to bypass international export restrictions.
- •The system's interconnect fabric, dubbed 'Ling-Link,' reportedly achieves a bi-directional bandwidth of 800 Gbps per node, significantly reducing latency for large-scale AI model training.
- •Lingsheng's cooling infrastructure employs an advanced liquid-to-chip immersion cooling solution, allowing the system to maintain a Power Usage Effectiveness (PUE) rating of 1.08.
- •The project received substantial funding under China's 14th Five-Year Plan, specifically targeting breakthroughs in exascale computing to support national research in climate modeling and drug discovery.
Competitor Analysis
- Lingsheng (China)
- RISC-V / Custom
- Frontier (USA)
- AMD EPYC / Instinct
- Aurora (USA)
- Intel Xeon / Max GPU
- Lingsheng (China)
2.0 Exaflops
- Frontier (USA)
- ~1.2 Exaflops
- Aurora (USA)
- ~1.0 Exaflops
- Lingsheng (China)
- Liquid Immersion
- Frontier (USA)
- Direct-to-Chip
- Aurora (USA)
- Direct-to-Chip
| Feature | Lingsheng (China) | Frontier (USA) | Aurora (USA) |
|---|---|---|---|
| Architecture | RISC-V / Custom | AMD EPYC / Instinct | Intel Xeon / Max GPU |
| Peak Performance | 2.0 Exaflops | ~1.2 Exaflops | ~1.0 Exaflops |
| Cooling | Liquid Immersion | Direct-to-Chip | Direct-to-Chip |
Technical Deep Dive
- Architecture: Heterogeneous design integrating custom RISC-V high-performance cores with proprietary tensor processing units.
- Interconnect: Ling-Link proprietary fabric utilizing optical switching technology for inter-node communication.
- Memory: Integrated HBM3e stacks providing 4.8 TB/s bandwidth per accelerator module.
- Power Efficiency: Achieved 1.08 PUE through full-immersion liquid cooling, minimizing thermal throttling during peak loads.
- Software Stack: Optimized for the 'Lingsheng-OS' kernel, a hardened Linux distribution with custom drivers for domestic AI acceleration hardware.
Future ImplicationsAI analysis grounded in cited sources
Timeline
- 2024-03Project Lingsheng officially initiated under the 14th Five-Year Plan.
- 2025-09Successful pilot test of the 'Ling-Link' interconnect fabric at 500 petaflops.
- 2026-05Full system integration and initial boot of the Lingsheng supercomputer.
- 2026-06Lingsheng officially surpasses the 2 exaflops performance threshold.
Weekly AI Recap
Read this week's curated digest of top AI events →
Related Updates
AI-curated news aggregator. All content rights belong to original publishers.
Original source: Pandaily ↗
This is a summary, not the original. Read the source, or get the weekly briefing.
The weekly digest
One email a week. Unsubscribe anytime.