Best practices for multi-turn RL in Amazon SageMaker AI
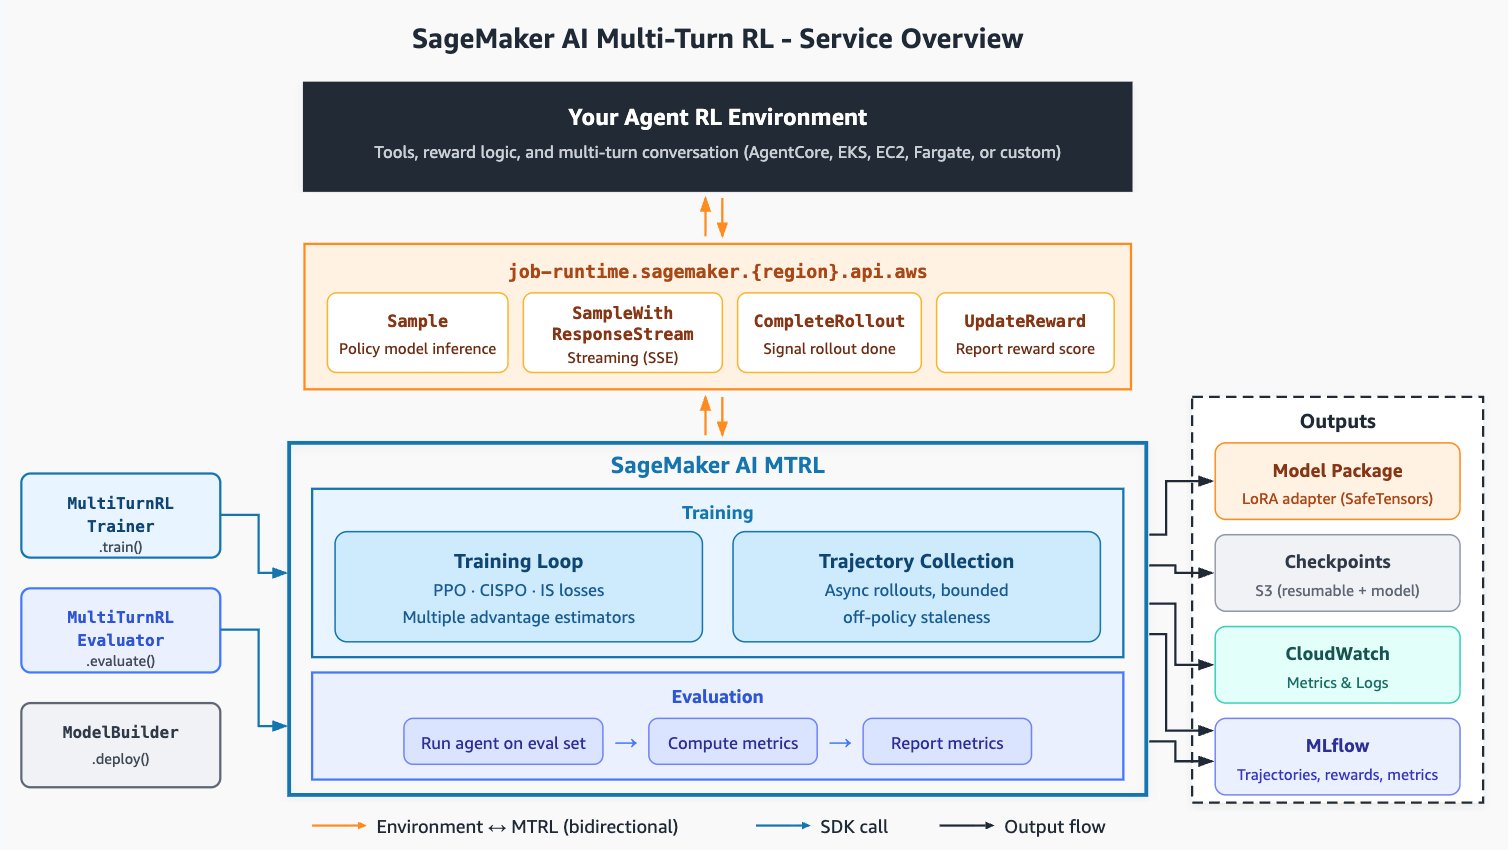
Master the complexities of multi-turn reinforcement learning with these expert-backed architectural best practices.
30-Second TL;DR
What Changed
Design rewards that align strictly with the end-task objectives
Why It Matters
Provides a structured approach for ML engineers to improve the reliability and performance of complex multi-turn RL agents.
What To Do Next
Review your current reward function design against the multi-turn evaluation strategies mentioned in the guide to reduce training instability.
Key Points
- •Design rewards that align strictly with the end-task objectives
- •Implement external evaluation frameworks to validate agent performance
- •Monitor specific metrics to determine when to iterate on the training environment
Deep Insight
AI-generated analysis for this event — not the original article.
Enhanced Key Takeaways
- •Amazon SageMaker AI integrates with the Ray RLlib library to facilitate distributed reinforcement learning, allowing for scalable multi-turn training across heterogeneous compute clusters.
- •The use of SageMaker Experiments is recommended to track hyperparameter configurations and reward function variations across multiple training runs, ensuring reproducibility in non-deterministic RL environments.
- •SageMaker's integration with Amazon CloudWatch allows for real-time monitoring of custom metrics such as episode reward mean and policy loss, which are critical for detecting training instability in multi-turn scenarios.
- •Best practices include the implementation of 'Reward Shaping' techniques to mitigate sparse reward signals, which are common in complex multi-turn tasks where the final outcome is delayed.
- •SageMaker AI supports the deployment of multi-turn RL models via Multi-Model Endpoints (MME), optimizing cost-efficiency when serving multiple specialized agents on shared infrastructure.
Competitor Analysis
- Amazon SageMaker AI
- Ray RLlib, Custom
- Google Vertex AI
- Ray, Custom
- Azure Machine Learning
- Ray, Custom
- Amazon SageMaker AI
- Highly Scalable
- Google Vertex AI
- Managed Ray Clusters
- Azure Machine Learning
- Managed Ray Clusters
- Amazon SageMaker AI
- SageMaker Experiments
- Google Vertex AI
- Vertex AI Experiments
- Azure Machine Learning
- Azure ML Experiments
- Amazon SageMaker AI
- Pay-as-you-go
- Google Vertex AI
- Pay-as-you-go
- Azure Machine Learning
- Pay-as-you-go
| Feature | Amazon SageMaker AI | Google Vertex AI | Azure Machine Learning |
|---|---|---|---|
| RL Framework Support | Ray RLlib, Custom | Ray, Custom | Ray, Custom |
| Distributed Training | Highly Scalable | Managed Ray Clusters | Managed Ray Clusters |
| Experiment Tracking | SageMaker Experiments | Vertex AI Experiments | Azure ML Experiments |
| Pricing Model | Pay-as-you-go | Pay-as-you-go | Pay-as-you-go |
Technical Deep Dive
- Utilization of the SageMaker RL container which pre-packages TensorFlow, PyTorch, and Ray RLlib environments.
- Support for custom environment wrappers using the OpenAI Gym/Gymnasium interface to define state spaces, action spaces, and reward logic.
- Integration with Amazon S3 for checkpointing model weights during long-running multi-turn training sessions to enable fault tolerance.
- Use of SageMaker Training Compiler to optimize the execution graph of RL policies, reducing latency in multi-turn inference cycles.
Future ImplicationsAI analysis grounded in cited sources
Timeline
- 2018-11AWS announces SageMaker RL, introducing managed reinforcement learning capabilities.
- 2020-12SageMaker adds support for distributed training with Ray on AWS.
- 2023-04AWS expands SageMaker's generative AI capabilities, influencing RL workflows.
- 2025-02SageMaker AI branding introduced, consolidating ML and generative AI services.
Weekly AI Recap
Read this week's curated digest of top AI events →
Related Updates
AI-curated news aggregator. All content rights belong to original publishers.
Original source: AWS Machine Learning Blog ↗
This is a summary, not the original. Read the source, or get the weekly briefing.
The weekly digest
One email a week. Unsubscribe anytime.