SourceInfoQ中国•Stalecollected in 0m
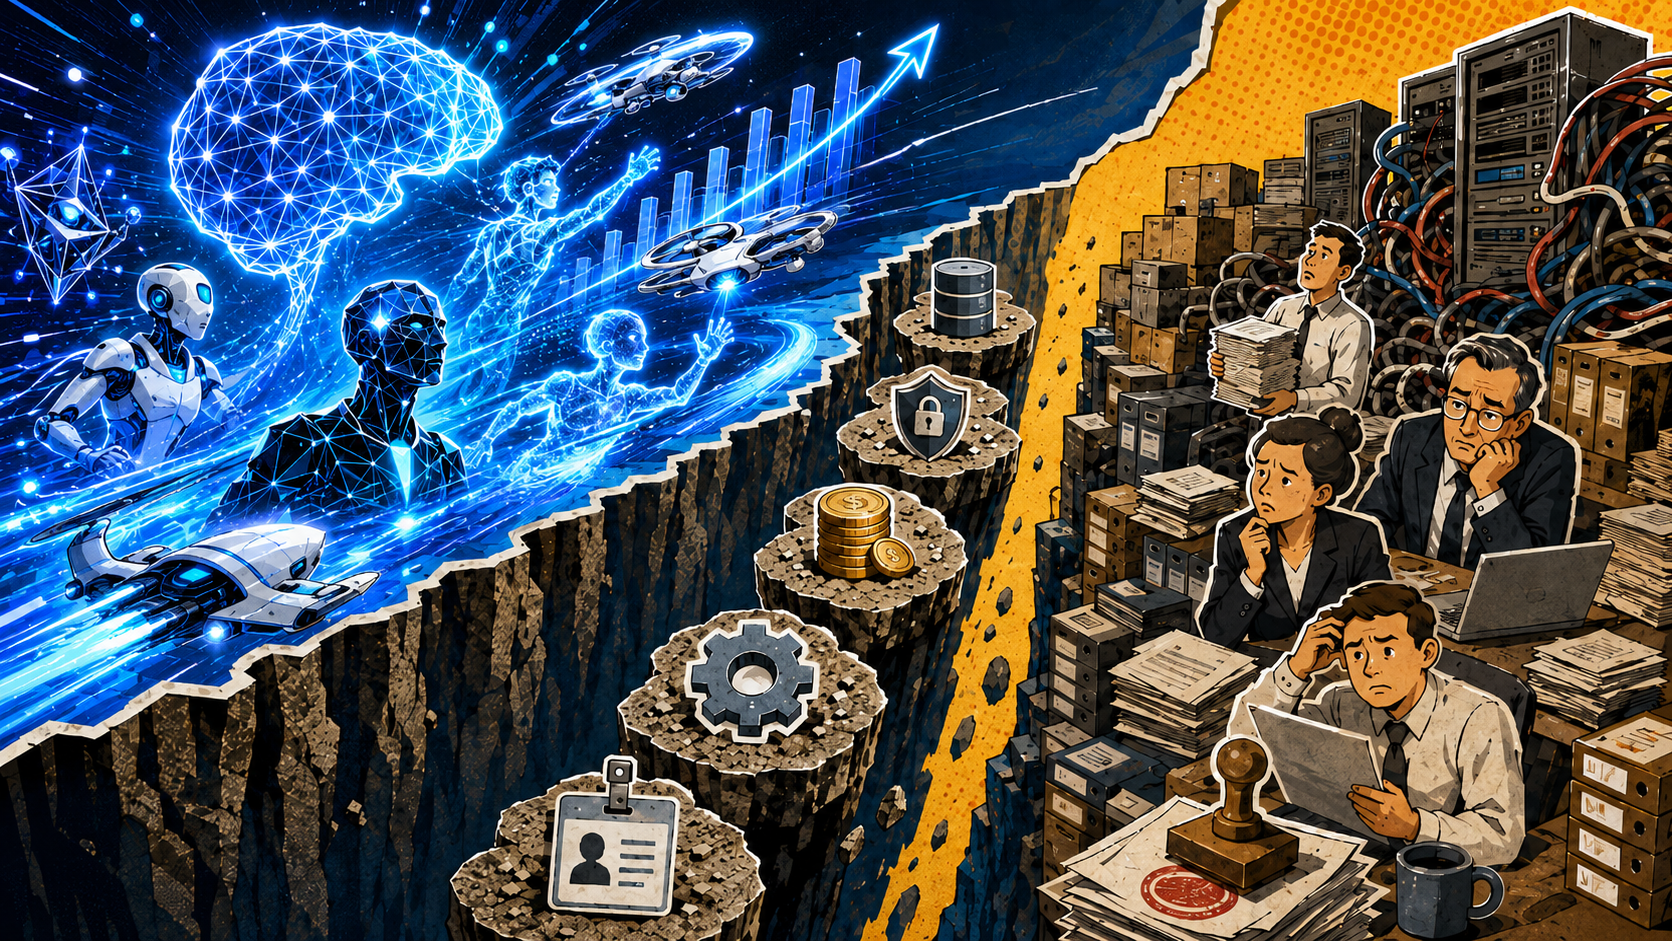
企業 AI 窗口正在快速收窄
#ai-maturity#enterprise-strategy企業-ai-成熟度分析enterprise-ai
AI 競爭窗口只剩 3 至 4 年,先確認你的團隊是否高估了自身準備程度。
30-Second TL;DR
What Changed
企業利用 AI 建立競爭優勢的時間窗口可能只剩 3 至 4 年
Why It Matters
這項判斷突顯企業不能只停留在 AI 試點或概念驗證階段。對 AI 團隊而言,真正的競爭力將取決於資料、工程流程、治理和部署能力能否快速規模化。
What To Do Next
在本週為團隊建立一份 AI 成熟度基準,逐項評估資料品質、模型部署、監控、治理與成本控制能力。
Who should care:Enterprise & Security Teams
Key Points
- •企業利用 AI 建立競爭優勢的時間窗口可能只剩 3 至 4 年
- •約 98% 的企業高估自身技術成熟度
- •企業需要正視 AI 能力評估與實際落地能力之間的差距
Deep Insight
AI-generated analysis for this event — not the original article.
Enhanced Key Takeaways
- •Recent advancements in diffusion-based video enhancement utilize 'Reference-Guided' architectures, which leverage high-quality keyframes to stabilize temporal flickering in AI-generated sequences.
- •New research indicates that incorporating 'Semantic-Aware' loss functions during the upscaling process prevents the degradation of fine textures like skin pores or fabric weaves that generic super-resolution models often blur.
- •The industry is shifting toward 'Hybrid Pipelines' where generative models are used for initial frame synthesis, followed by specialized 'De-artifacting' neural networks trained specifically on common GAN and Diffusion noise patterns.
- •Temporal consistency is increasingly being addressed through 'Optical Flow Guided' refinement, which ensures that motion vectors remain coherent across frames during the enhancement process.
- •Standard metrics like PSNR and SSIM are being replaced by 'Perceptual Video Quality' (PVQ) metrics, which better correlate with human subjective evaluation of AI-generated motion artifacts.
Technical Deep Dive
- Architecture: Integration of Temporal Attention Layers within the super-resolution backbone to maintain inter-frame coherence.
- Loss Functions: Utilization of LPIPS (Learned Perceptual Image Patch Similarity) combined with temporal consistency loss to penalize motion jitter.
- Data Processing: Implementation of multi-scale feature fusion, allowing the model to process low-resolution structural information and high-resolution texture details separately.
- Training Strategy: Use of synthetic degradation datasets that mimic specific AI artifacts (e.g., 'hallucinated' edges, color bleeding, and latent space noise) rather than traditional Gaussian blur.
Future ImplicationsAI analysis grounded in cited sources
Real-time AI video enhancement will become a standard feature in consumer-grade video editing software by 2027.
The rapid optimization of inference-efficient architectures like Distilled Diffusion models is significantly lowering the compute barrier for local hardware.
Generative video models will begin to incorporate 'Self-Enhancement' modules directly into their inference loops.
By integrating enhancement layers into the generation pipeline, models can correct artifacts before the final frame is decoded, reducing the need for post-processing.
Timeline
2023-05
Early adoption of diffusion-based super-resolution for static image upscaling.
2024-09
Introduction of temporal-aware video upscaling models addressing frame-to-frame flickering.
2025-11
Emergence of specialized datasets focused on training models to remove AI-specific generation artifacts.
2026-04
Standardization of perceptual quality metrics for evaluating AI-generated video fidelity.
- 2023-05Early adoption of diffusion-based super-resolution for static image upscaling.
- 2024-09Introduction of temporal-aware video upscaling models addressing frame-to-frame flickering.
- 2025-11Emergence of specialized datasets focused on training models to remove AI-specific generation artifacts.
- 2026-04Standardization of perceptual quality metrics for evaluating AI-generated video fidelity.
Weekly AI Recap
Read this week's curated digest of top AI events →
AI-curated news aggregator. All content rights belong to original publishers.
Original source: InfoQ中国 ↗
This is a summary, not the original. Read the source, or get the weekly briefing.
The weekly digest
One email a week. Unsubscribe anytime.