來源ITmedia AI+ (日本)•較早收集於 46m
Google 發布 Gemma 4 的 MTP,文字生成速度提升最高 3 倍
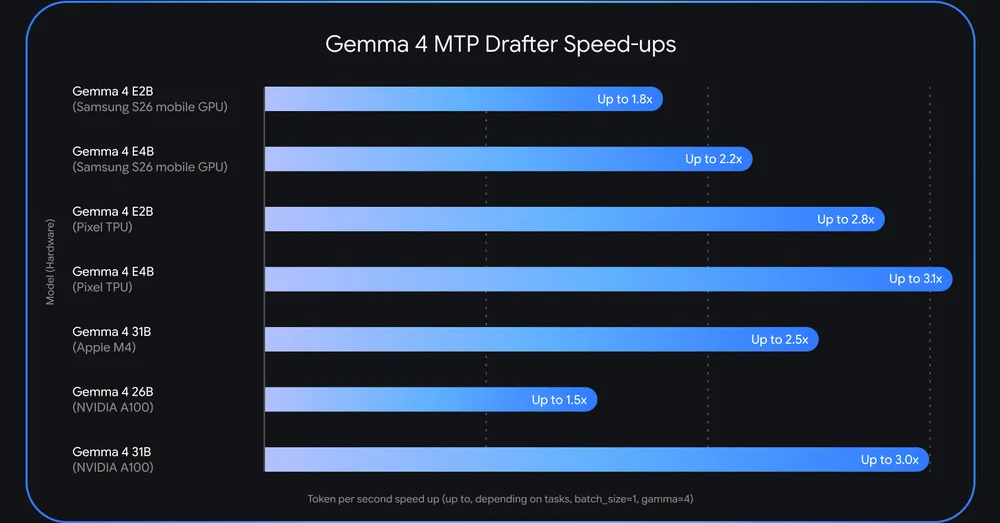
Gemma 4 推論加速 3 倍!MTP 優化開源 LLM,立即部署!(28 字元)
30 秒速覽
有什麼變化
為 Gemma 4 開源模型發布 MTP 草稿器
為什麼重要
這提升 Gemma 4 在實際部署中的效率,在無品質損失下實現更快推論。開源從業者在資源受限環境中獲得競爭優勢。
下一步行動
透過 vLLM 或 TensorRT-LLM 將 MTP 整合至 Gemma 4 管線,獲得 3 倍推論加速。
誰應關注:Developers & AI Engineers
關鍵要點
- •為 Gemma 4 開源模型發布 MTP 草稿器
- •文字生成速度提升最高 3 倍
- •採用投機性解碼進行並行推論
- •維持生成品質
- •相容主要框架,從邊緣到雲端
深度解析
本篇為 AI 生成分析,非原文內容。
增強重點摘要
- •The MTP implementation for Gemma 4 utilizes a lightweight 'drafter' head architecture that is trained concurrently with the main model, specifically designed to predict the next k-tokens simultaneously rather than sequentially.
- •Integration with inference engines like vLLM and TensorRT-LLM is achieved through a standardized API, allowing developers to swap drafter weights without modifying the underlying model architecture.
- •Performance benchmarks indicate that the 3x speedup is most pronounced in high-throughput scenarios where the KV cache memory bandwidth is the primary bottleneck, rather than compute-bound tasks.
競品分析
Mechanism
- Google Gemma 4 MTP
- Multi-Token Prediction (MTP)
- Meta Llama 3 Speculative Decoding
- Standard Speculative Decoding
- Mistral Speculative Decoding
- Standard Speculative Decoding
Drafter Model
- Google Gemma 4 MTP
- Integrated/Trained with base
- Meta Llama 3 Speculative Decoding
- External/Small model required
- Mistral Speculative Decoding
- External/Small model required
Framework Support
- Google Gemma 4 MTP
- Native (vLLM, TensorRT-LLM)
- Meta Llama 3 Speculative Decoding
- Broad (vLLM, HuggingFace)
- Mistral Speculative Decoding
- Broad (vLLM, HuggingFace)
Efficiency Gain
- Google Gemma 4 MTP
- Up to 3x (Context dependent)
- Meta Llama 3 Speculative Decoding
- 1.5x - 2.5x
- Mistral Speculative Decoding
- 1.5x - 2.5x
| Feature | Google Gemma 4 MTP | Meta Llama 3 Speculative Decoding | Mistral Speculative Decoding |
|---|---|---|---|
| Mechanism | Multi-Token Prediction (MTP) | Standard Speculative Decoding | Standard Speculative Decoding |
| Drafter Model | Integrated/Trained with base | External/Small model required | External/Small model required |
| Framework Support | Native (vLLM, TensorRT-LLM) | Broad (vLLM, HuggingFace) | Broad (vLLM, HuggingFace) |
| Efficiency Gain | Up to 3x (Context dependent) | 1.5x - 2.5x | 1.5x - 2.5x |
技術深入
- •Architecture: Employs a shared transformer backbone with a specialized MTP head that outputs multiple tokens in a single forward pass.
- •Training: The MTP head is trained using a multi-token loss function, forcing the model to learn dependencies between consecutive tokens during the pre-training phase.
- •Inference Logic: During speculative decoding, the drafter proposes a sequence of tokens; the main model validates these in parallel, accepting the longest prefix that matches the target distribution.
- •Memory Overhead: The MTP head adds negligible parameter count (typically <5% of total model size), ensuring minimal impact on VRAM footprint.
前景展望基於引用來源的 AI 分析
MTP will become the standard for all future open-weight model releases.
The significant latency reduction provided by MTP without sacrificing accuracy creates a competitive necessity for model providers to include drafter heads.
Edge device inference performance will see a 2x increase in token generation rates.
By reducing the number of sequential memory-bound forward passes, MTP allows memory-constrained edge hardware to utilize more compute cycles for token validation.
時間線
2024-02
Google releases the initial Gemma open model family.
2025-03
Google announces Gemma 3 with improved architectural efficiency.
2026-02
Google launches Gemma 4, focusing on native multi-token prediction capabilities.
2026-05
Google releases the optimized MTP drafter for Gemma 4 to the public.
- 2024-02Google releases the initial Gemma open model family.
- 2025-03Google announces Gemma 3 with improved architectural efficiency.
- 2026-02Google launches Gemma 4, focusing on native multi-token prediction capabilities.
- 2026-05Google releases the optimized MTP drafter for Gemma 4 to the public.
AI 週報
閱讀本週精選 AI 大事摘要 →
相關動態
AI 策展新聞聚合。所有內容版權歸原始發布者所有。
原始來源: ITmedia AI+ (日本) ↗
每週電子報
每週一封,可隨時退訂。