SourceAWS Machine Learning Blog•Stalecollected in 10m
Speculative Decoding Boosts LLM Inference
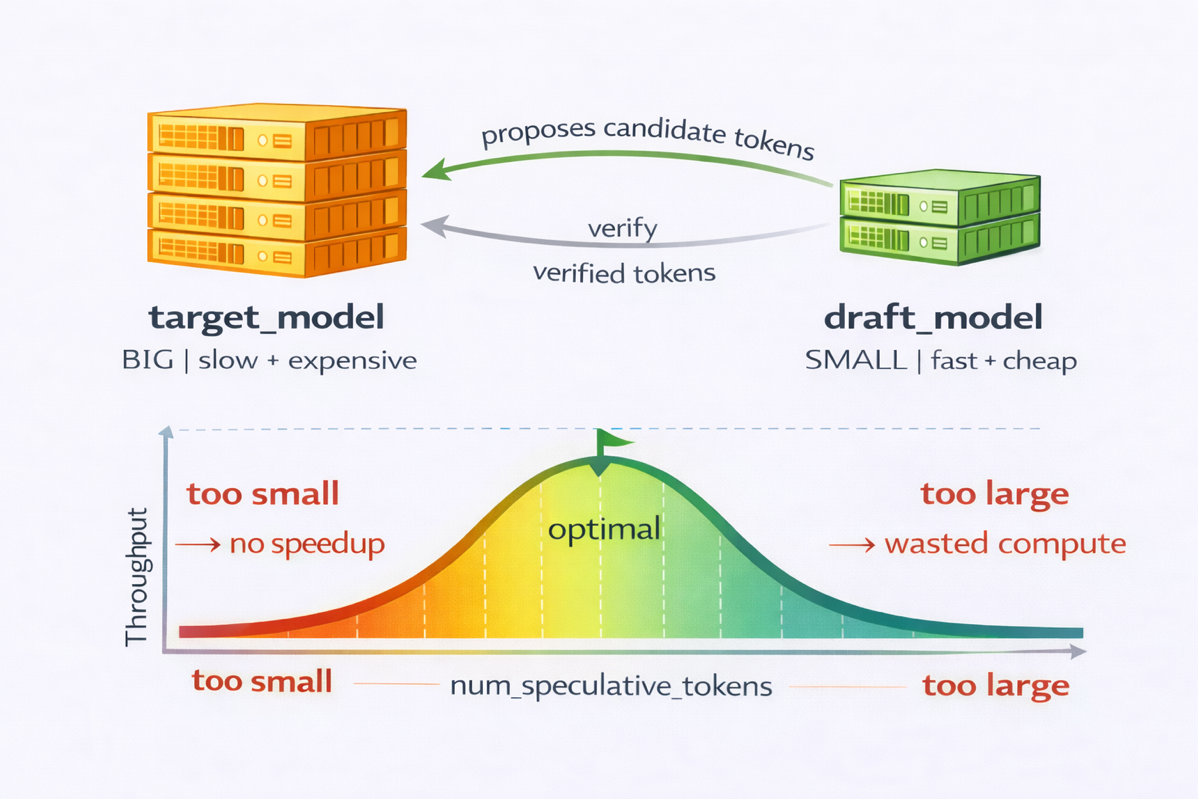
#speculative-decoding#inference#trainiumaws-trainium2aws-trainium2vllmllm
Cut LLM token costs 2x+ via speculative decoding on Trainium2 + vLLM
30-Second TL;DR
What Changed
Speculative decoding optimizes decode-heavy LLM inference
Why It Matters
Lowers inference costs for production LLMs on Trainium2. Enables faster, cheaper deployments for AI practitioners scaling generative AI apps.
What To Do Next
Deploy vLLM with speculative decoding on Trainium2 to cut LLM inference costs.
Who should care:Developers & AI Engineers
Key Points
- •Speculative decoding optimizes decode-heavy LLM inference
- •Integrated with vLLM on AWS Trainium2
- •Reduces cost per generated token significantly
Weekly AI Recap
Read this week's curated digest of top AI events →
Related Updates
AI-curated news aggregator. All content rights belong to original publishers.
Original source: AWS Machine Learning Blog ↗
This is a summary, not the original. Read the source, or get the weekly briefing.
The weekly digest
One email a week. Unsubscribe anytime.