來源Engadget•較早收集於 2h
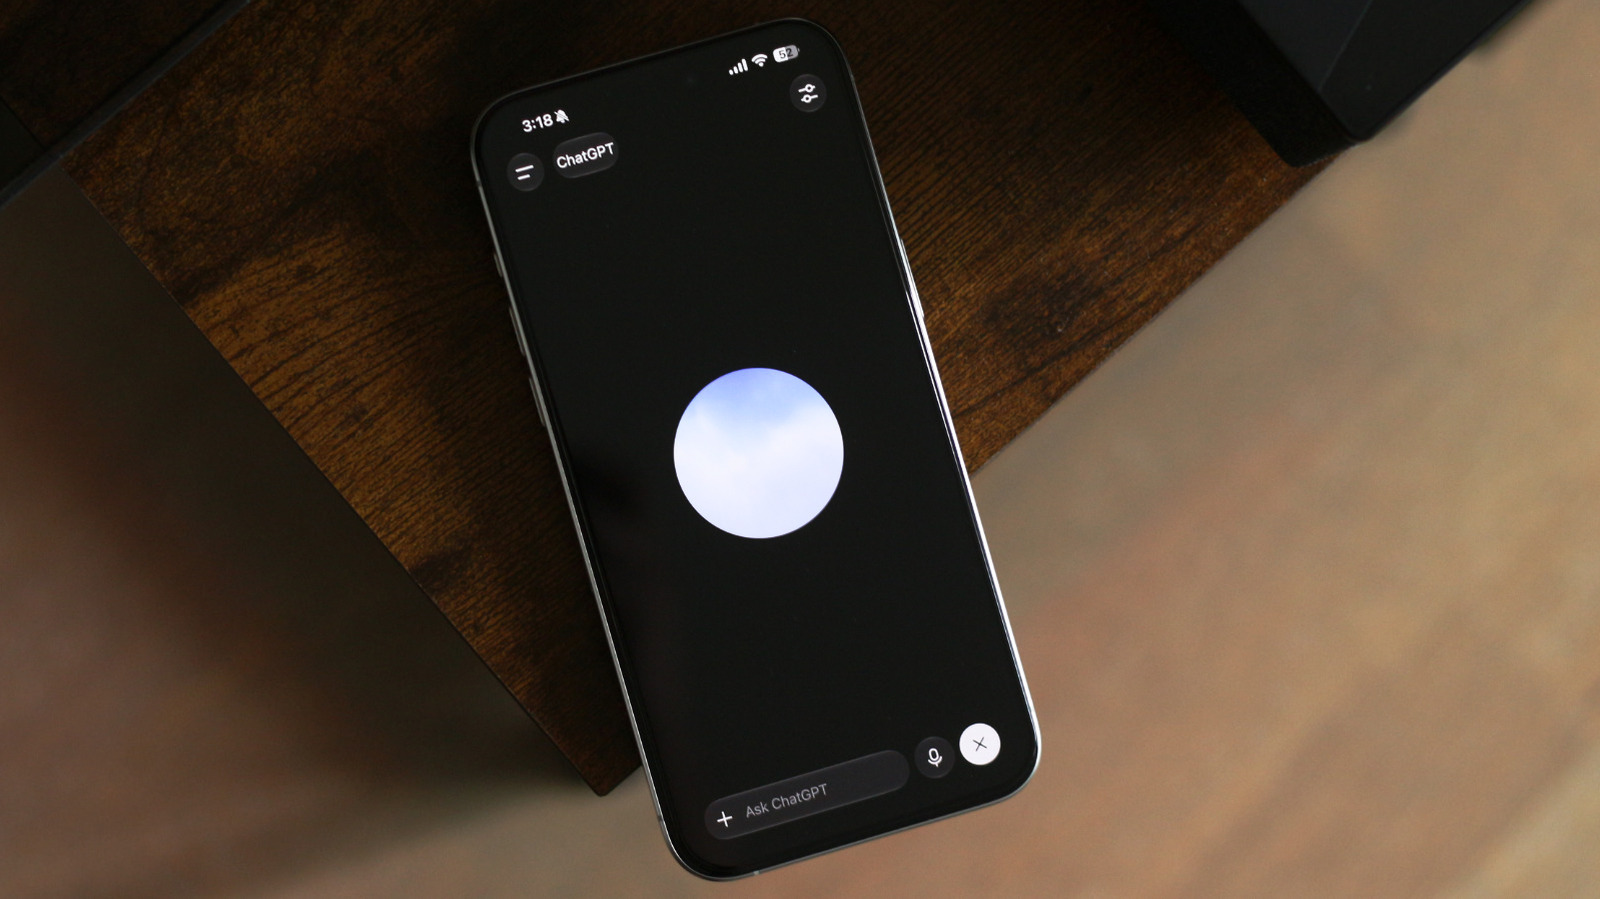
ChatGPT 語音模式變得更自然
#voice-mode#conversational-ai#voice-interfacechatgptopenaichatgpt
了解 ChatGPT 更新後的語音模式,如何讓語音 AI 互動變得更自然。
30 秒速覽
有什麼變化
ChatGPT 語音模式旨在讓語音對話變得更自然、減少尷尬感。
為什麼重要
更自然的語音互動有助於提升可及性,並讓 ChatGPT 更適合免持操作、語言練習及對話式應用。AI 實務工作者也能將此功能視為設計低摩擦語音介面的參考。
下一步行動
開啟 ChatGPT 並在免持操作流程中測試語音模式,將回應自然度、打斷處理能力及任務完成度與現有語音介面比較。
誰應關注:Developers & AI Engineers
關鍵要點
- •ChatGPT 語音模式旨在讓語音對話變得更自然、減少尷尬感。
- •使用者可以透過對話式語音交流與 ChatGPT 互動。
- •文章提供啟用及使用更新後語音模式的實用說明。
深度解析
本篇為 AI 生成分析,非原文內容。
增強重點摘要
- •The updated Voice Mode utilizes OpenAI's GPT-4o (Omni) model, which enables native multimodal processing to handle audio, vision, and text in real-time without separate transcription steps.
- •Latency has been significantly reduced, allowing the model to respond to audio inputs in as little as 232 milliseconds, mimicking human-like conversational reaction times.
- •The system incorporates emotional intelligence capabilities, allowing the model to detect user tone and adjust its own vocal inflection, pacing, and emphasis accordingly.
- •OpenAI implemented advanced safety guardrails, including voice filtering and content moderation, to prevent the generation of harmful, copyrighted, or impersonated audio content.
- •The feature supports real-time interruptions, enabling users to speak over the AI to change the topic or correct the model mid-sentence, a significant departure from previous turn-based voice interfaces.
競品分析
Multimodal Latency
- ChatGPT (Advanced Voice)
- Ultra-low (Native)
- Google Gemini Live
- Low
- Anthropic Claude
- N/A (Text-focused)
Emotional Inflection
- ChatGPT (Advanced Voice)
- High
- Google Gemini Live
- Moderate
- Anthropic Claude
- N/A
Interruptibility
- ChatGPT (Advanced Voice)
- Yes
- Google Gemini Live
- Yes
- Anthropic Claude
- No
Pricing
- ChatGPT (Advanced Voice)
- Plus/Team/Enterprise
- Google Gemini Live
- Gemini Advanced
- Anthropic Claude
- N/A
| Feature | ChatGPT (Advanced Voice) | Google Gemini Live | Anthropic Claude |
|---|---|---|---|
| Multimodal Latency | Ultra-low (Native) | Low | N/A (Text-focused) |
| Emotional Inflection | High | Moderate | N/A |
| Interruptibility | Yes | Yes | No |
| Pricing | Plus/Team/Enterprise | Gemini Advanced | N/A |
技術深入
- Architecture: Utilizes a single end-to-end neural network trained across text, audio, and images, eliminating the need for separate ASR (Automatic Speech Recognition) and TTS (Text-to-Speech) pipelines.
- Audio Processing: Processes raw audio waveforms directly, which preserves paralinguistic cues like laughter, singing, and varying emotional states.
- Tokenization: Employs a specialized audio tokenizer that compresses audio data into a format compatible with the transformer architecture while maintaining high fidelity.
- Inference: Runs on optimized GPU clusters to maintain sub-second latency, utilizing speculative decoding to speed up response generation.
前景展望基於引用來源的 AI 分析
Voice-first interfaces will surpass text-based inputs for mobile productivity by 2027.
The reduction in latency and increase in emotional nuance make voice interactions significantly more efficient and less cognitively demanding than typing on mobile devices.
AI voice models will trigger new regulatory frameworks regarding biometric voice synthesis.
As AI voices become indistinguishable from human speech, governments will likely mandate watermarking or mandatory disclosure requirements to prevent fraud and deepfake exploitation.
時間線
2023-09
OpenAI introduces the initial version of ChatGPT Voice, allowing users to speak with the model.
2024-05
OpenAI announces GPT-4o, featuring native multimodal capabilities and significantly improved voice responsiveness.
2024-09
Advanced Voice Mode begins rolling out to ChatGPT Plus and Team users.
2025-05
OpenAI expands Voice Mode availability to include free-tier users with usage limits.
2026-02
Integration of 'Memory' features allows Voice Mode to recall user preferences across different sessions.
- 2023-09OpenAI introduces the initial version of ChatGPT Voice, allowing users to speak with the model.
- 2024-05OpenAI announces GPT-4o, featuring native multimodal capabilities and significantly improved voice responsiveness.
- 2024-09Advanced Voice Mode begins rolling out to ChatGPT Plus and Team users.
- 2025-05OpenAI expands Voice Mode availability to include free-tier users with usage limits.
- 2026-02Integration of 'Memory' features allows Voice Mode to recall user preferences across different sessions.
AI 週報
閱讀本週精選 AI 大事摘要 →
相關動態
AI 策展新聞聚合。所有內容版權歸原始發布者所有。
原始來源: Engadget ↗
每週電子報
每週一封,可隨時退訂。