應用
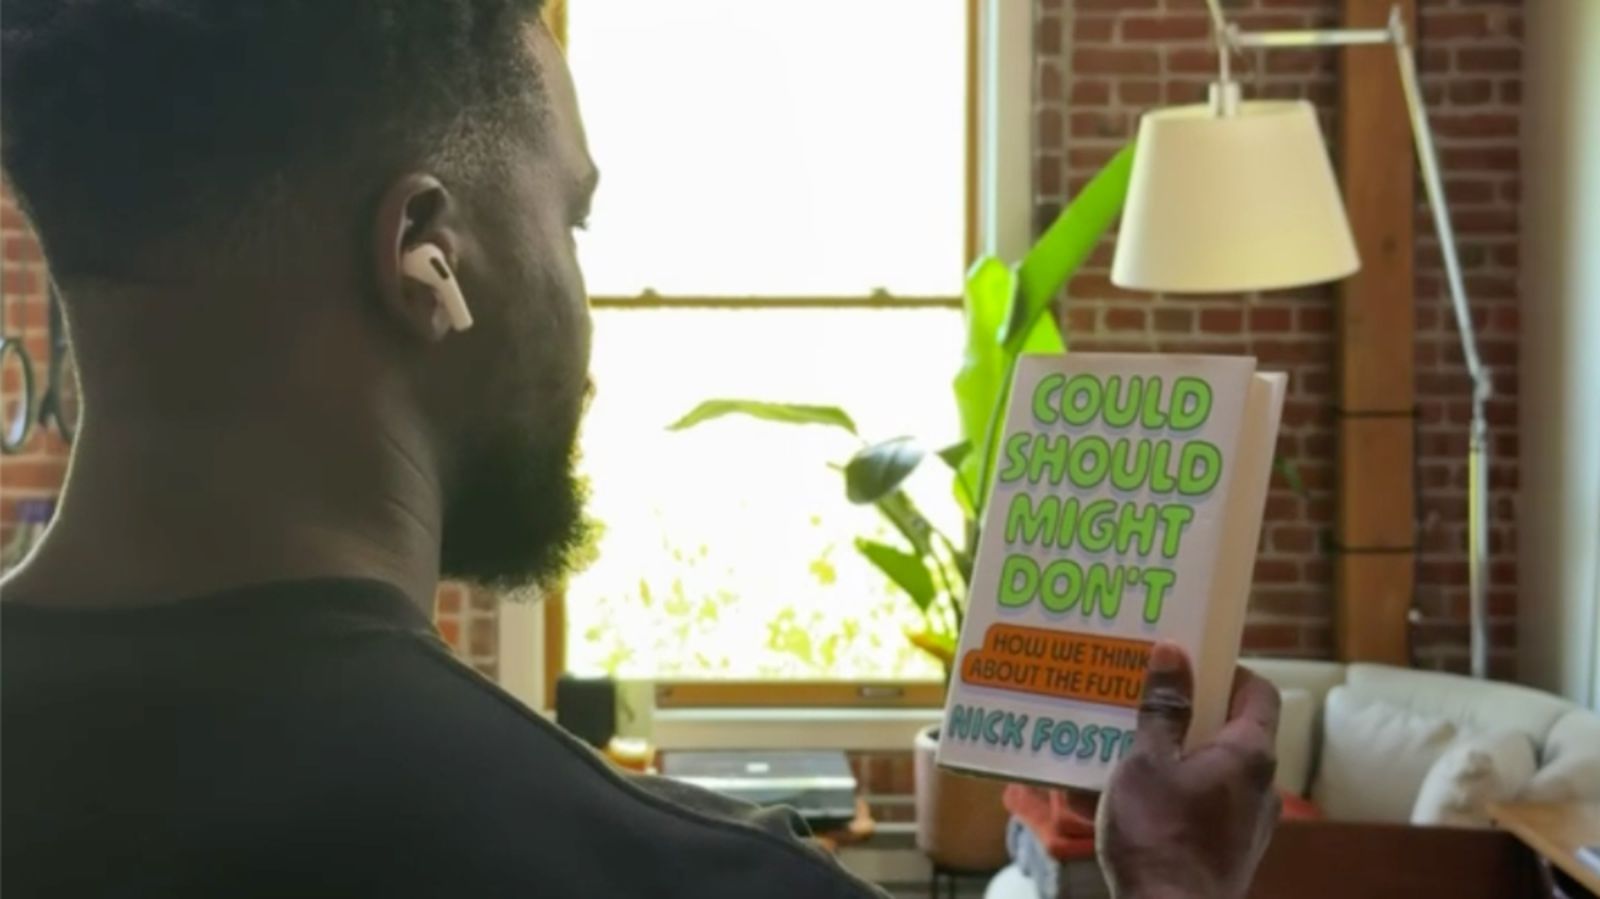
配備攝影機的 AirPods 實機示範曝光,或於 9 月亮相
據報 Apple 即將推出配備攝影機的 AirPods。macOS Tahoe 26.7 候選發布版本中被發現一段隱藏的實機示範影片,暗示產品可能於 9 月亮相。
cnBeta (Full RSS) · 33 天前
能看、能聽、能說的模型正在取代純文字系統。覆蓋視覺語言模型、原生音頻與視頻理解進展。
354 篇文章
據報 Apple 即將推出配備攝影機的 AirPods。macOS Tahoe 26.7 候選發布版本中被發現一段隱藏的實機示範影片,暗示產品可能於 9 月亮相。
cnBeta (Full RSS) · 33 天前
一篇 Reddit 貼文建議 Google 推出具開放權重的 120B dense multimodal Gemma 模型。這項構想目前仍屬推測,但認為西方企業可能更偏好 Google 品牌的模型,而非中國開源模型或 OpenAI、Anthropic 等封閉式服務。
Reddit r/LocalLLaMA · 35 天前
Google Images 慶祝其 25 週年,回顧了從單純的搜尋工具演變為複雜視覺探索平台的過程。此次更新強調了視覺搜尋技術的里程碑,並預告了與視覺內容互動的新方式。
Google AI Blog · 67 天前

一位用戶報告稱,透過利用 Gemini 獲取個人化護理建議,成功養活了室內植物。AI 協助診斷問題並提供量身定制的植物維護時間表。
Digital Trends · 67 天前

Reddit 正在推出一項新功能,允許用戶使用影片回覆留言。此更新旨在提升 DIY、教學與視覺演示類社群的互動性。
Digital Trends · 100 天前

本文探討了配備鏡頭的 AI 耳機作為智慧型手機替代品的實際可行性。作者透過 72 小時的佩戴體驗,評估了這類穿戴式 AI 裝置目前的局限性與潛力。
Ifanr (爱范儿) · 116 天前

愛範兒預告 GPT-5 終於能以自然人話說話。內容顯示「請稍等片刻」訊息。
Ifanr (爱范儿) · 135 天前

GPT-Image-2 最火玩法是看手相,AI 從手部影像給出過度奉承的運勢預測。用戶被正面回饋逗樂,突顯多模態 AI 的創意應用。
Ifanr (爱范儿) · 145 天前

詩歌相機是一款外觀迷人、復古風格的小工具,看似玩樂相機,實際上從拍攝場景生成 AI 詩歌並打印在熱敏收據紙上,而非照片。其白底櫻桃紅配色與編織肩帶極具吸引力。
The Verge · 155 天前

TechRadar 作家使用 ChatGPT 將孩子的粗糙動物塗鴉轉換成驚人逼真的寫實生物。AI 保留了原始繪畫的本質,沒有大幅改變。
TechRadar AI · 157 天前

一款自製 AI 老婆 App 用於教授任意語言,採用 Gemma-4-E4B-it 作為 LLM、經 FastAPI 的 OmniVoice TTS,以及 Vroid Studio 3D 模型。支援圖片上傳、網路搜尋,以及類似 Grok Ani 的語音/視訊通話。
Reddit r/LocalLLaMA · 162 天前
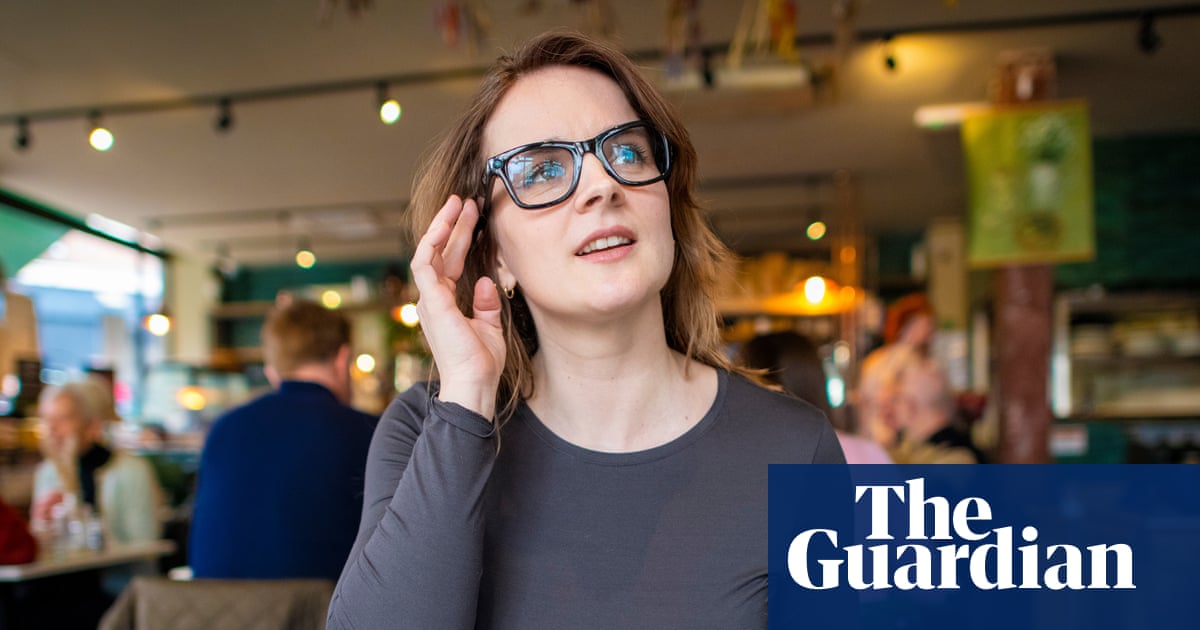
評測者戴Meta智慧眼鏡一個月,其內建AI助理由Judi Dench配音,提供導航、天氣更新及場景描述。內容創作者喜愛內建相機,但批評者稱其為「變態眼鏡」。
The Guardian Technology · 171 天前

賽力斯汽車公布基於情緒識別的智能座艙控制專利。透過影片提取生理與面部特徵,實現非接觸式情緒偵測。
36氪 · 194 天前

Alibaba launches Qwen3.5-Plus, dominating open-source benchmarks in multimodal understanding, reasoning, coding, and agents, rivaling closed models like GPT-5.2. Priced at 0.8 RMB per million tokens, it's 18x cheaper than Gemini 3 Pro.
机器之心 · 215 天前
Alibaba's Qwen3.5-Plus launches as top open-source model in multimodal, reasoning, coding, and agents. Priced at 0.8 yuan per million tokens, it's 18x cheaper than Gemini 3 Pro.
机器之心 · 215 天前

ByteDance's Seed 2.0 debuts at #6 text and #3 vision on LM Arena, highest for Chinese models. Native multimodal excels in math, vision perception, reasoning, and agents, matching Gemini 3 Pro and GPT 5.2.
机器之心 · 215 天前
ByteDance's Seed 2.0 debuts at #6 text, #3 vision on LMArena, leading domestic models. Excels in math, vision perception, reasoning, and agents, matching Gemini 3 Pro.
机器之心 · 215 天前

ByteDance launches Doubao 2.0, a major multimodal Agent model upgrade with Seedance 2.0 video and Seedream 5.0 Lite image generation. It excels in multimodal understanding, enterprise Agents, and code reasoning.
机器之心 · 217 天前
After 21 months of development, Doubao large model officially enters its 2.0 era. It claims the highest scores in visual benchmarks.
量子位 · 217 天前
Doubao large model enters 2.0 era after 21 months of development. It claims the highest score in vision benchmarks.
量子位 · 217 天前
ByteDance's Doubao large model officially advances to 2.0 after 21 months of development. It claims the highest scores in visual benchmarks.
量子位 · 217 天前

Ohio State and Amazon release MMDR-Bench, a verifiable benchmark for multimodal Deep Research Agents. Focuses on process traceability, evidence alignment, and claim verification beyond superficial reports.
机器之心 · 217 天前

MAPLE is a modality-aware ecosystem for post-training multimodal LLMs, including MAPLE-bench, MAPO optimization, and adaptive curricula. It stratifies training by modality needs to cut variance and speed convergence.
ArXiv AI · 218 天前
Introduces BLPO to optimize prompts for multimodal LLM-as-a-judge evaluating AI images. Overcomes context limits by converting images to text representations.
ArXiv AI · 218 天前